The Difference Between AI Transparency and Useful Proof
AI transparency is not enough. Learn how useful proof helps users verify AI output, trust decisions and move from review to action.
Your AI feature is being inspected, not adopted. Users open details, read explanations, maybe expand the source panel. Then they copy nothing, apply nothing and go back to the old workflow. On paper you added AI transparency. In practice you did not give them proof they could use.
This is a common AI product adoption failure: the product answers internal accountability questions, but not the user's next decision. A model label, confidence number, safety note or reasoning summary can make the system look more open. It does not tell a busy user whether this specific answer is safe to send, edit, cite, merge, publish or ignore.
AI transparency is not the same as useful proof
Transparency is about visibility into the system. Useful proof is about evidence for action. The gap matters because users do not adopt AI output by understanding it in the abstract. They adopt it when they can decide what to do next with low enough risk.
AI transparency usually says something like: this was generated by AI, these inputs were used, this is how confident the system is, this is the source list, this is the reasoning summary. Those details can help, but only if they reduce the user's verification work.
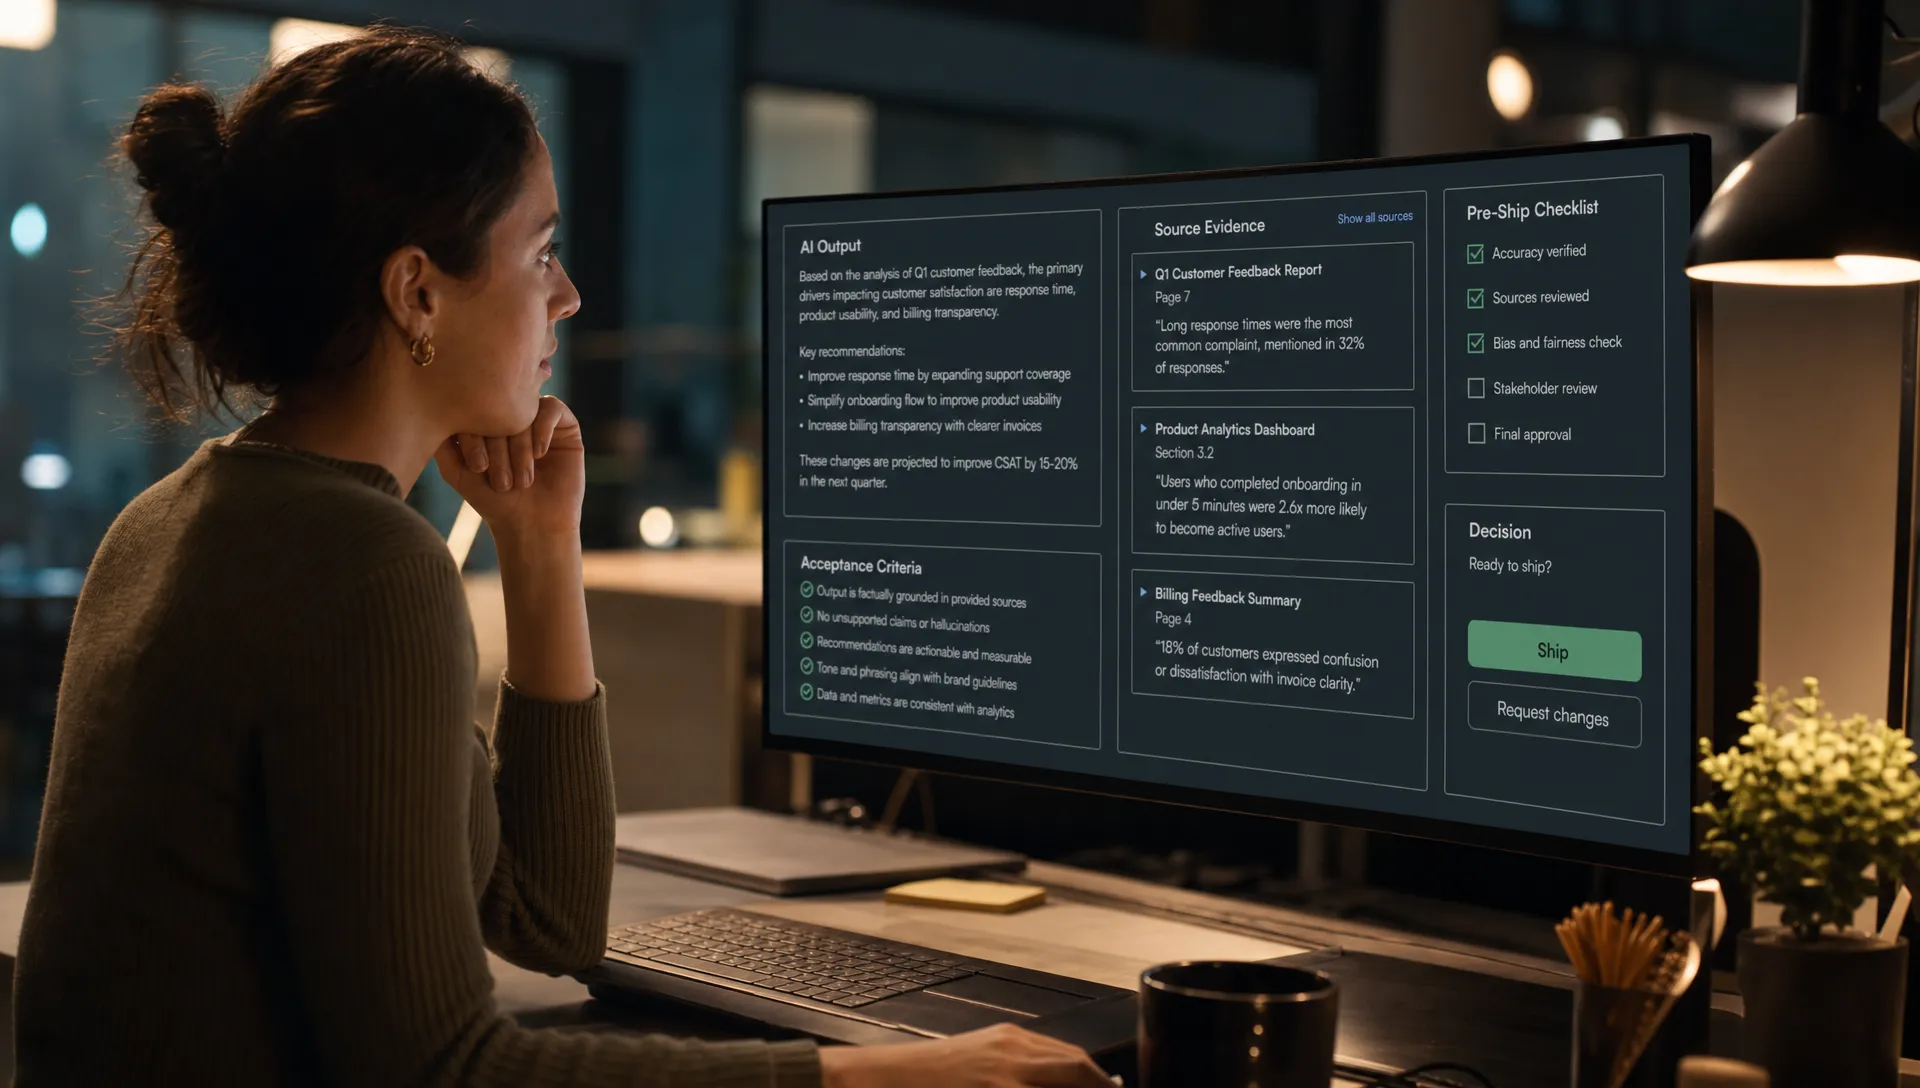
Useful proof is narrower and more practical. It says: this claim came from this passage, this edit changed only tone and not legal meaning, this code suggestion compiles against the current file, this summary omitted these sections, this recommendation is based on the last 30 days rather than all history.
If this sounds close to the explainability problem, it is. The deeper issue is covered in AI explainability is useless if users still cannot act: an explanation that does not change the next safe action is mostly decoration.
The failure pattern: users inspect, then abandon
A transparency feature often creates the feeling that trust has been handled. The UI has a disclosure. The output has a badge. There is a confidence score. Legal, security and product all feel better.
Then the usage data says otherwise. Users keep generating. They rarely accept. They paste output into another tool to check it. They ask the same question multiple ways. They create manual review rituals outside the product. This is not curiosity. It is unresolved risk.
| User behavior | What the team thinks it means | What it often means |
|---|---|---|
| Users open the rationale panel but do not apply the output | They want more explanation | They are looking for evidence the UI does not provide |
| Users regenerate three or more times | They want a better answer | They cannot tell which answer is safe enough |
| Users copy output into docs, spreadsheets or search | They prefer their own workflow | They need external verification before use |
| Users ask very narrow prompts | They are becoming power users | They are constraining the AI because trust is low |
| Users accept simple outputs but avoid important ones | Quality is inconsistent | The proof level does not match the decision risk |
The adoption break is not always output quality. It is often proof quality. The answer may be good, but the user cannot prove that quickly enough.
Useful proof is evidence tied to a decision
Useful proof starts with a product question: what decision does the user need to make at this moment?
For a researcher, the decision may be whether a claim is citeable. For a sales manager, it may be whether an account summary is current enough to brief a rep. For a developer, it may be whether a code suggestion is safe to accept without breaking nearby logic. For a support lead, it may be whether an AI reply is accurate enough to send to a customer.
That means proof is not one UI component. It is a fit between evidence and risk. A citation can be proof in a research product. A diff can be proof in a writing product. A test result can be proof in a coding product. A data freshness label can be proof in an analytics product.
What useful proof looks like in real products
Perplexity feels more verifiable than many answer engines because citations sit near the claims they support. The user does not need to hunt for the review step. The proof is placed where doubt appears. It is not perfect, but it makes the next action obvious: inspect the source, compare the claim and decide whether to use it.
Grammarly works well in lower risk writing moments because it shows the proposed change before the user accepts it. The proof is the diff. You can see what will change. That is more useful than a generic statement that the system improved clarity.
GitHub Copilot and Cursor depend on a different proof pattern. Developers do not need a long explanation of the model. They need local context, readable diffs, tests, compiler feedback and easy rollback. In this setting, useful proof is not a confidence score. It is whether the suggestion survives the developer's normal acceptance checks.
The pattern is the same across categories. Proof works when it is close to the output, matched to the task and cheap to inspect. If users must leave the workflow to validate the answer, the product has transferred the adoption cost back to them.
Diagnostic: which trust problem do you have?
Before adding another transparency feature, diagnose the failure. The same surface symptom can come from different causes.
| Symptom in the product | Likely trust problem | Better response |
|---|---|---|
| High generation, low acceptance | Users like the idea but cannot verify the result | Add proof at the point of acceptance |
| High acceptance, high undo or edit rate | Users try the output but find hidden errors later | Show what changed and make recovery easier |
| Users only use AI for low stakes tasks | Proof does not scale to higher risk decisions | Add stronger evidence for higher impact actions |
| Users ask for sources on every answer | The source path is not obvious enough | Put source evidence next to the claim |
| Users ignore confidence scores | The score is not connected to a clear action | Replace or pair it with task-specific checks |
This is where many AI onboarding strategies go wrong. They teach users what the AI can do, but not how to know when to use it. Onboarding that says generate a summary is weaker than onboarding that says check these three highlighted passages before sending the summary.
How to design useful proof without adding clutter
More proof does not mean more interface. A dense explanation panel can make adoption worse because it adds review work without resolving the decision.
Start by mapping the moment where the user hesitates. Is it before generation, after generation, before applying or after applying? Proof belongs at the hesitation point. If the user gets nervous before sending a customer reply, do not hide evidence in a settings page.
Then choose the right proof type. Source proof helps when claims matter. Change proof helps when edits matter. Scope proof helps when omissions matter. Execution proof helps when code, workflow actions or automations matter. Recovery proof helps when the user fears being stuck with a bad AI action.
A useful proof pattern usually answers five product questions:
- What exactly is the user being asked to accept?
- What evidence would make that acceptance safe enough?
- Where does doubt appear in the workflow?
- Can the user inspect proof without leaving the task?
- What happens if the AI was wrong?
The last question is often missed. Trust is easier when recovery is clear. Undo, partial accept, preview, approval queues and audit history are not just safety features. They are adoption features.
If your team is working on this specific trust break, the practical design question is not how do we make the AI more transparent. It is how do we verify AI output with less friction and more trust at the exact point where the user decides.
Do not overuse confidence scores
Confidence scores are tempting because they look compact. One number appears to solve a messy trust problem. In many product contexts, it does not.
A 92 percent confidence score rarely tells a user what to do. Should they send the email? Merge the code? Quote the summary? Escalate the account? The number may even create liability if users treat it as permission without understanding its limits.
If you use confidence, tie it to a specific action. For example: high confidence because the answer is supported by three recent sources, low confidence because no source matched the requested date range, review needed because the generated policy answer touches a restricted topic. Now the label is not just transparent. It supports a decision.
FAQ
Is AI transparency still useful? Yes, but it is not sufficient. Transparency helps users understand that AI was involved and may expose inputs, sources or limitations. Useful proof goes further by helping the user decide whether this output is safe to use right now.
What is the fastest way to find a proof gap? Look for the moment where users stop. If they generate but do not accept, the proof gap is near acceptance. If they accept but undo later, the gap is after application. If they avoid important tasks, the proof level is too weak for the risk.
Are citations always useful proof? No. Citations help when source-backed claims matter. They are less useful for style edits, code changes, data transformations or workflow actions. The proof type has to match the user's decision.
Should every AI output include a detailed explanation? No. Detailed explanations can increase cognitive load. In many cases, users need a source snippet, diff, preview, test result or rollback path more than they need a model explanation.
Next action
Pick one high value AI workflow where adoption is weaker than expected. Do not start by rewriting the prompt or improving the model. Watch what users do after the output appears. If they pause, regenerate, copy elsewhere or over-edit, write down what proof they are trying to create manually.
Then replace that manual proof step with a product decision. Put the evidence closer to the output. Make the review step smaller. Make recovery obvious.
If you want a structured way to do this across the product, the AI Product Adoption Deck includes diagnostics, action cards and workshops for trust, verification, onboarding and retention breaks. The goal is not more AI transparency. The goal is output users can prove enough to use.