AI Autonomy Should Match the Cost of Being Wrong
AI product adoption stalls when autonomy exceeds risk. Learn how to match AI control to error cost, review needs and recovery paths.
Users tried the feature. They liked the demo. Some saved the output. But when the product asked to send, publish, update, delete or decide for them, they stopped. That is not a generic AI product adoption problem. It is an autonomy mismatch: the product is asking for more agency than the user can safely grant.
The model may be good enough. The workflow may be real. The UX may be clean. But if the cost of being wrong is high, users will not hand over control just because the output looks plausible.
The symptom: users like the AI but refuse to let it act
This shows up in product data before it shows up in interviews.
Users generate drafts but do not send them. They accept suggestions in private docs but avoid using the same feature in customer-facing work. They ask the AI to analyze a spreadsheet then manually recheck every cell. They run the automation once, get nervous, and switch back to the old workflow.
The misleading read is “users do not trust AI.” That is too broad to be useful.
A sharper read is this: users trust the system at one level of autonomy but not the next. They may trust it to propose. They may not trust it to commit. They may trust it when the mistake is easy to spot. They may not trust it when the mistake becomes visible to a customer, boss, regulator or production system.
If your AI feature has strong trial and weak repeat use, look at the autonomy you are asking for before you blame onboarding, prompt quality or model accuracy.
Autonomy is not one product setting
Teams often talk about AI autonomy as if it is binary. Manual or automated. Copilot or autopilot. That framing hides the real design choice.
AI autonomy is a ladder. Each rung changes who notices the mistake, who fixes it and who is accountable for the result.
| Autonomy level | What the AI does | User posture | Good fit |
|---|---|---|---|
| Suggest | Recommends an option | User chooses | Low commitment decisions |
| Draft | Produces editable work | User revises | Writing, planning, analysis |
| Prepare action | Sets up the next step | User approves | Emails, tickets, reports |
| Execute with guardrails | Takes action inside limits | User monitors | Repeated operational tasks |
| Execute autonomously | Acts without review | User audits later | Low-risk, reversible workflows |
Most AI adoption problems happen when the product jumps two rungs too fast. A user who is comfortable with draft assistance may not be ready for autonomous execution. That does not mean the feature is bad. It means the product skipped the trust bridge.
This is also why comparing your product to GitHub Copilot, Grammarly or Notion AI can mislead you. In many usage patterns, those tools keep the user close to the decision. The user accepts, edits, rejects or rewrites before the work lands. The AI is powerful, but the commitment point still belongs to the human.
That ownership matters. If you are designing an AI workflow where the user remains accountable, the trust problem is different from a workflow where the system acts on their behalf. This is why users trust AI differently when they own the decision.
The real variable is the cost of being wrong
Accuracy alone does not tell you how much autonomy to give the system. A 95 percent correct AI step may be fine for tagging internal notes. It may be unacceptable for sending pricing terms to a customer.
The cost of being wrong is not only financial. It includes embarrassment, time loss, damaged relationships, compliance exposure and loss of user confidence. It also includes how hard the mistake is to detect.
Use these dimensions before deciding how much control the AI should have.
| Risk dimension | Low cost of being wrong | High cost of being wrong |
|---|---|---|
| Visibility | Private to the user | Visible to customers, executives or the public |
| Reversibility | Easy undo or edit | Hard to retract, delete or explain |
| Detectability | Mistake is obvious | Mistake looks plausible until later |
| Frequency | Rare one-off action | Repeated action that compounds errors |
| Accountability | Product absorbs the consequence | User owns the consequence |
| Context sensitivity | Generic task | Depends on policy, relationship or timing |
The product decision follows from the table. High autonomy belongs where errors are low cost, reversible and easy to detect. Low autonomy belongs where errors are expensive, public or hard to catch.
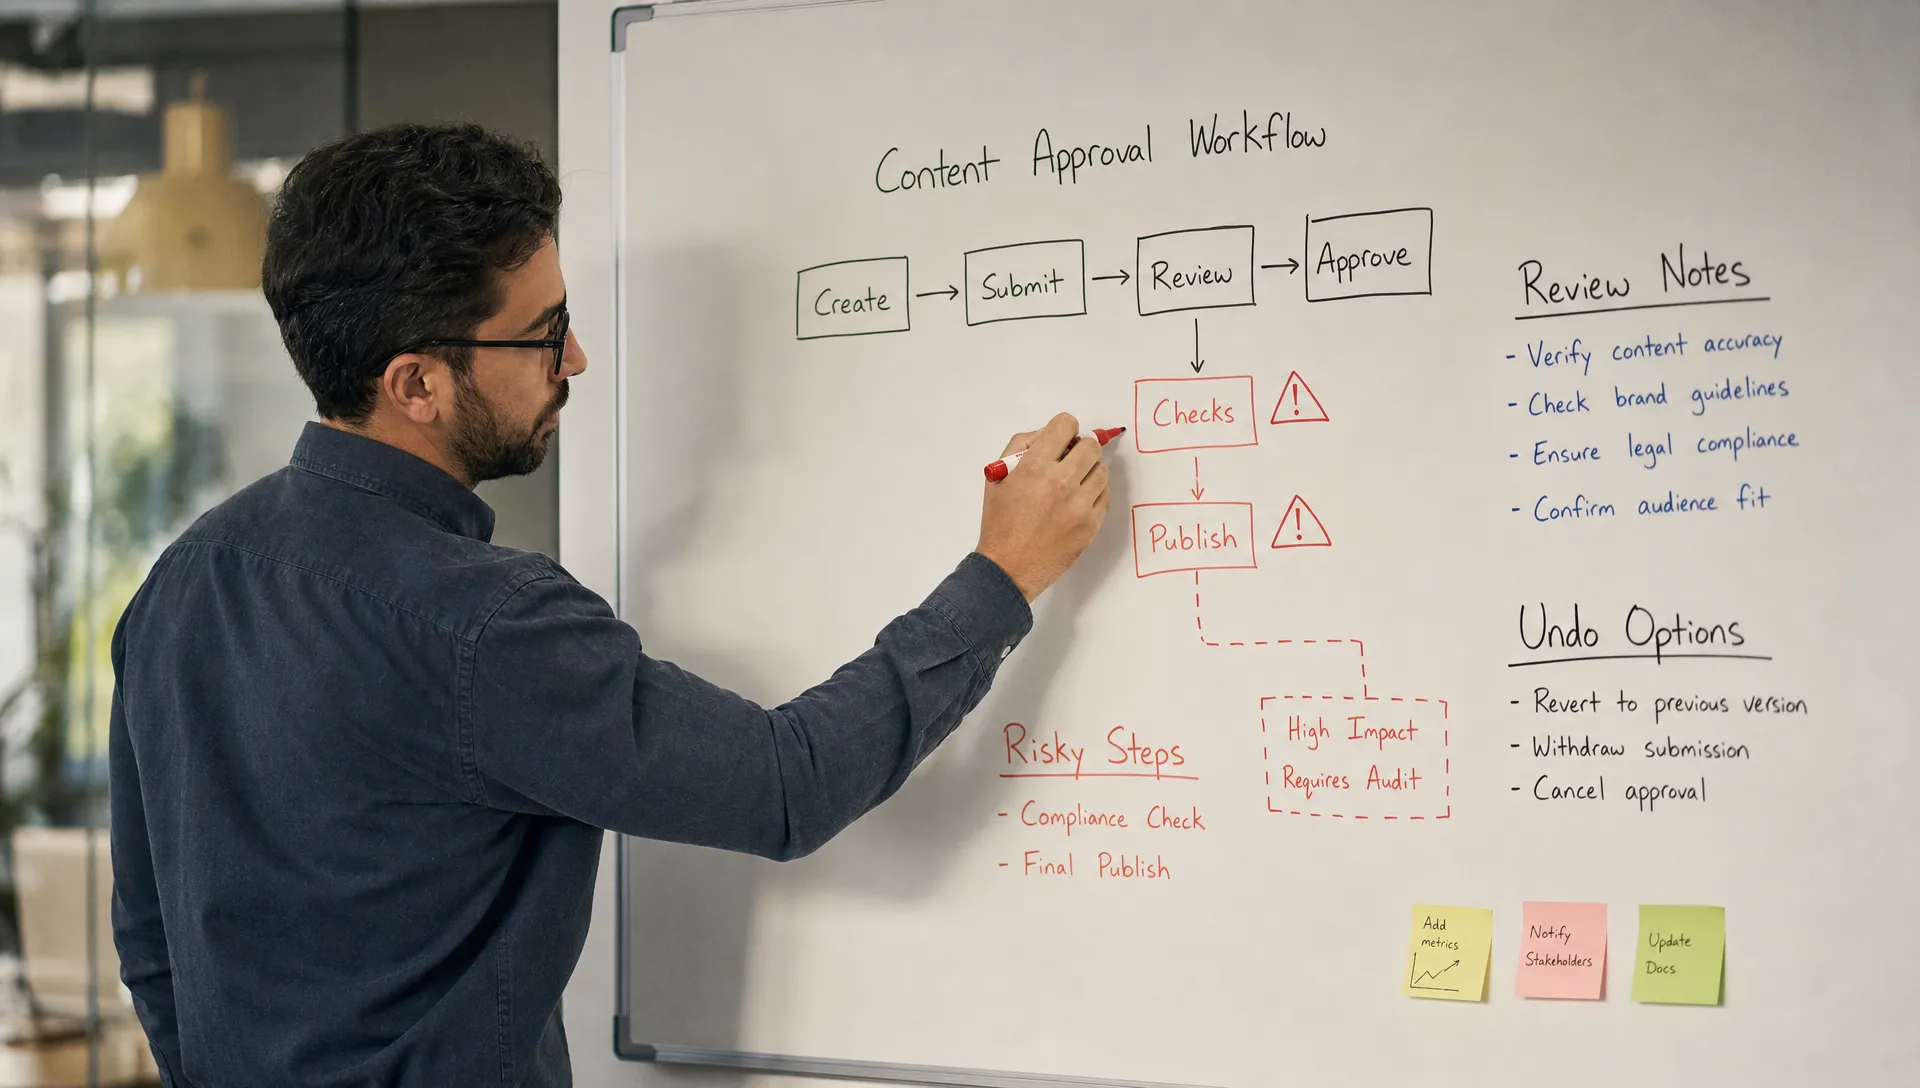
Match the interface to the risk
Once you know the cost of being wrong, the interface should make the autonomy level obvious. Do not bury the control model in a tooltip or settings panel. Users need to understand what the AI can do before they hand it the workflow.
For low-risk tasks, speed matters. Let the AI act quickly. Reduce ceremony. Put undo nearby. Do not force review steps that make the AI slower than the manual path.
For medium-risk tasks, use a prepare-and-approve pattern. The AI can assemble the email, create the ticket, classify the lead or draft the plan. The user sees the proposed action and commits it. This keeps momentum without pretending the system should own the outcome.
For high-risk tasks, constrain the AI before it acts. Let users set scope, exclusions, audience, tone, data access and approval rules. The user should not feel like they are supervising an unpredictable agent. They should feel like they are delegating a bounded job.
This is where many AI onboarding strategies fall short. They teach the user how to prompt, but not how control works. A better first-run experience answers four questions fast: what can the AI change, what can it only suggest, what happens before anything is sent and how do I reverse it?
If users cannot set that boundary, trust breaks even when the output is useful. The pattern is covered more directly in AI and Trust Break When Users Cannot Set a Safe Boundary.
The metrics that reveal an autonomy mismatch
You do not need a six-week research project to spot this. Your event data will usually show the gap.
Look for these patterns:
- High generation rate with low approval, send or publish rate
- Long delay between AI output and user action
- Heavy editing before commit, even on simple tasks
- Repeated previews of the same output without execution
- Users copying output into another tool instead of using the built-in action
- Strong activation but weak second-week retention
The last one matters. A user may try an AI feature because it is novel or because the demo is clear. Habit forms only when the user believes the system fits the risk of the job.
For example, an AI that drafts customer replies might see strong first-use numbers. Users like seeing a complete response. But if the product pushes one-click send before users trust tone, policy fit and account context, the workflow stalls. The right fix may not be a better model. It may be a safer handoff: draft, show source context, highlight assumptions and require approval before sending.
That is also why confidence scores rarely solve the problem by themselves. A confidence score says the system feels sure. It does not give the user a path to inspect, correct or recover. Trust tends to come from what happens after a mistake, not from a number before it. If recovery is the weak point in your product, start with how trust in AI comes from recovery, not a new badge.
A simple decision frame for product teams
Before you increase AI autonomy, answer these questions in order.
First, what is the committed action? Be specific. “Help with sales” is not a product action. “Send a follow-up email to an open opportunity” is.
Second, who pays for the mistake? If the user carries the social, legal or business consequence, assume they will demand more control.
Third, can the user detect the mistake before it matters? Plausible wrongness is more dangerous than obvious failure. A weird draft is easy to fix. A subtly wrong renewal clause is not.
Fourth, can the product recover cleanly? Undo, audit trail, version history, approvals and escalation paths are not secondary UI. They are what make higher autonomy usable.
Fifth, what is the smallest safe rung on the autonomy ladder? Start there. Let behavior prove that users are ready for more.
This frame keeps the team out of the common trap: shipping an “agentic” workflow because it looks more impressive than a controlled assistant. Impressive does not equal adopted. For many B2B products, the winning AI product tactic is not more autonomy. It is the right autonomy at the right moment.
Frequently Asked Questions
How much autonomy should an AI feature have? Give the AI as much autonomy as the user can safely grant for that specific action. Low-cost, reversible tasks can support more automation. High-cost, public or hard-to-detect mistakes need review, boundaries and recovery paths.
Is low AI autonomy bad for adoption? No. Low autonomy can improve adoption when users are accountable for the result. Many successful AI workflows begin as suggestions or drafts because that matches how users build trust.
What is the difference between an AI trust problem and an autonomy mismatch? A trust problem is broad. An autonomy mismatch is specific: users trust the AI for one job, such as drafting, but not for a higher-risk job, such as sending or changing records.
Which AI adoption metrics help diagnose this? Watch the gap between generation and committed action. Preview rate, approval rate, edit depth, undo rate, time to commit and repeat use are more useful than raw feature clicks.
The next action
Pick one AI workflow in your product and name the action the AI is trying to take. Then score the cost of being wrong. If the cost is high, do not start by pushing users toward autopilot. Add clearer boundaries, approval points and recovery paths.
If you want a faster way to diagnose where your adoption is breaking, run the symptom through the free AI adoption triage tool. If you want to go deeper with your team, the AI Product Adoption Deck includes diagnostics, action cards and workshops for turning these patterns into product decisions.