Why AI Trust Depends on Who Sees the Final Output
AI product adoption often breaks when users fear who will see the final output. Diagnose trust gaps by audience, risk and review step.
Your users are not rejecting the AI because the output is useless. They are rejecting it at the moment it becomes visible to someone else.
That difference matters for AI product adoption. A user may happily use an AI draft for private thinking, then freeze before pasting it into a client email, a board memo, a pull request or a customer-facing response. Same output. Same model. Different audience. Trust changes because the cost of being wrong changes.
If your metrics show strong generation but weak send, publish, export or share behavior, you may not have an output quality problem. You may have a final-audience problem.
The trust problem starts with who will judge the work
AI trust is often discussed as if it belongs between the user and the model. In real products, it usually sits between the user and the person who will see the result.
A support rep does not ask, “Is this AI answer good?” They ask, “Will this customer accept this answer if it is wrong, vague or oddly phrased?”
A PM using AI to summarize research does not only ask whether the summary is accurate. They ask whether their VP will spot a missing nuance in the next roadmap review.
A developer using Copilot does not only judge the suggestion in the editor. They think about code review, production behavior and who gets paged if the shortcut breaks something.
This is why trust can look high in private usage and low in workflow completion. The user is not evaluating the AI in isolation. They are evaluating the social and operational risk of letting that output leave their hands.
Why final output audience changes AI trust
The final viewer changes three things at once: the standard of correctness, the cost of correction and the user’s sense of ownership.
| Who sees the final output | What the user worries about | Common adoption symptom | Better product response |
|---|---|---|---|
| Only the user | “Can I use this to think faster?” | High generation, frequent iteration | Fast drafting, easy regeneration, lightweight editing |
| Internal teammate | “Will this make me look careless?” | Copying into another tool for cleanup | Style controls, review notes, change tracking |
| Manager or executive | “Will this miss context I should have known?” | Outputs saved but not shared | Source visibility, assumptions, decision caveats |
| Customer or prospect | “Will this damage trust if it is wrong?” | Drafts abandoned before send | Approval flow, tone guardrails, factual checks |
| Regulated or legal audience | “Can I defend this later?” | AI avoided for final work | Audit trail, citations, human signoff |
NIST’s AI Risk Management Framework makes this point in formal terms: AI risk depends on context. Product teams need to translate that into interface decisions. The same AI output can be acceptable as a private sketch and unacceptable as a final artifact.
The output is not just content. It is a liability transfer.
When users move AI output from draft to final, they accept responsibility for it. That handoff is where many AI features break.
In private mode, the AI can be rough. It can be incomplete. It can help the user think. The user still feels in control because nothing has been committed.
In final mode, the output starts to represent the user. It may represent the company too. A clumsy sentence becomes the user’s tone. A fabricated detail becomes the user’s mistake. A missing edge case becomes the user’s negligence.
This is why generic “high confidence” labels rarely move behavior. The user is not asking whether the model feels confident. They are asking whether they can stand behind the output in front of the person who will judge it.
If you want a deeper version of this ownership problem, the related pattern is covered in how users trust AI differently when they own the decision. The short version: users trust AI less when they cannot delegate accountability with the task.
Private usefulness does not predict shared trust
A common mistake is to measure adoption too early in the workflow. Teams count generations, prompt submissions or accepted suggestions, then assume trust is improving.
Those metrics can hide the break. Users may generate five versions, copy none of them and write the final message themselves. They may use AI to brainstorm, then remove every trace before sharing. They may accept an AI suggestion locally, then rewrite it during review.
That is not fake usage. It is real value at the private-work layer. But it is not the same as trust in final output.
Products like Grammarly understand this better than many AI tools. The suggestion sits close to the user’s own writing. The user can accept, reject or adjust small changes before the final text leaves. The product does not ask the user to trust a large opaque block. It lets them preserve authorship.
Perplexity works differently, but the trust move is similar. It makes review part of the output by putting sources near the answer. The answer is not treated as self-justifying. The user can inspect the evidence before they reuse it.
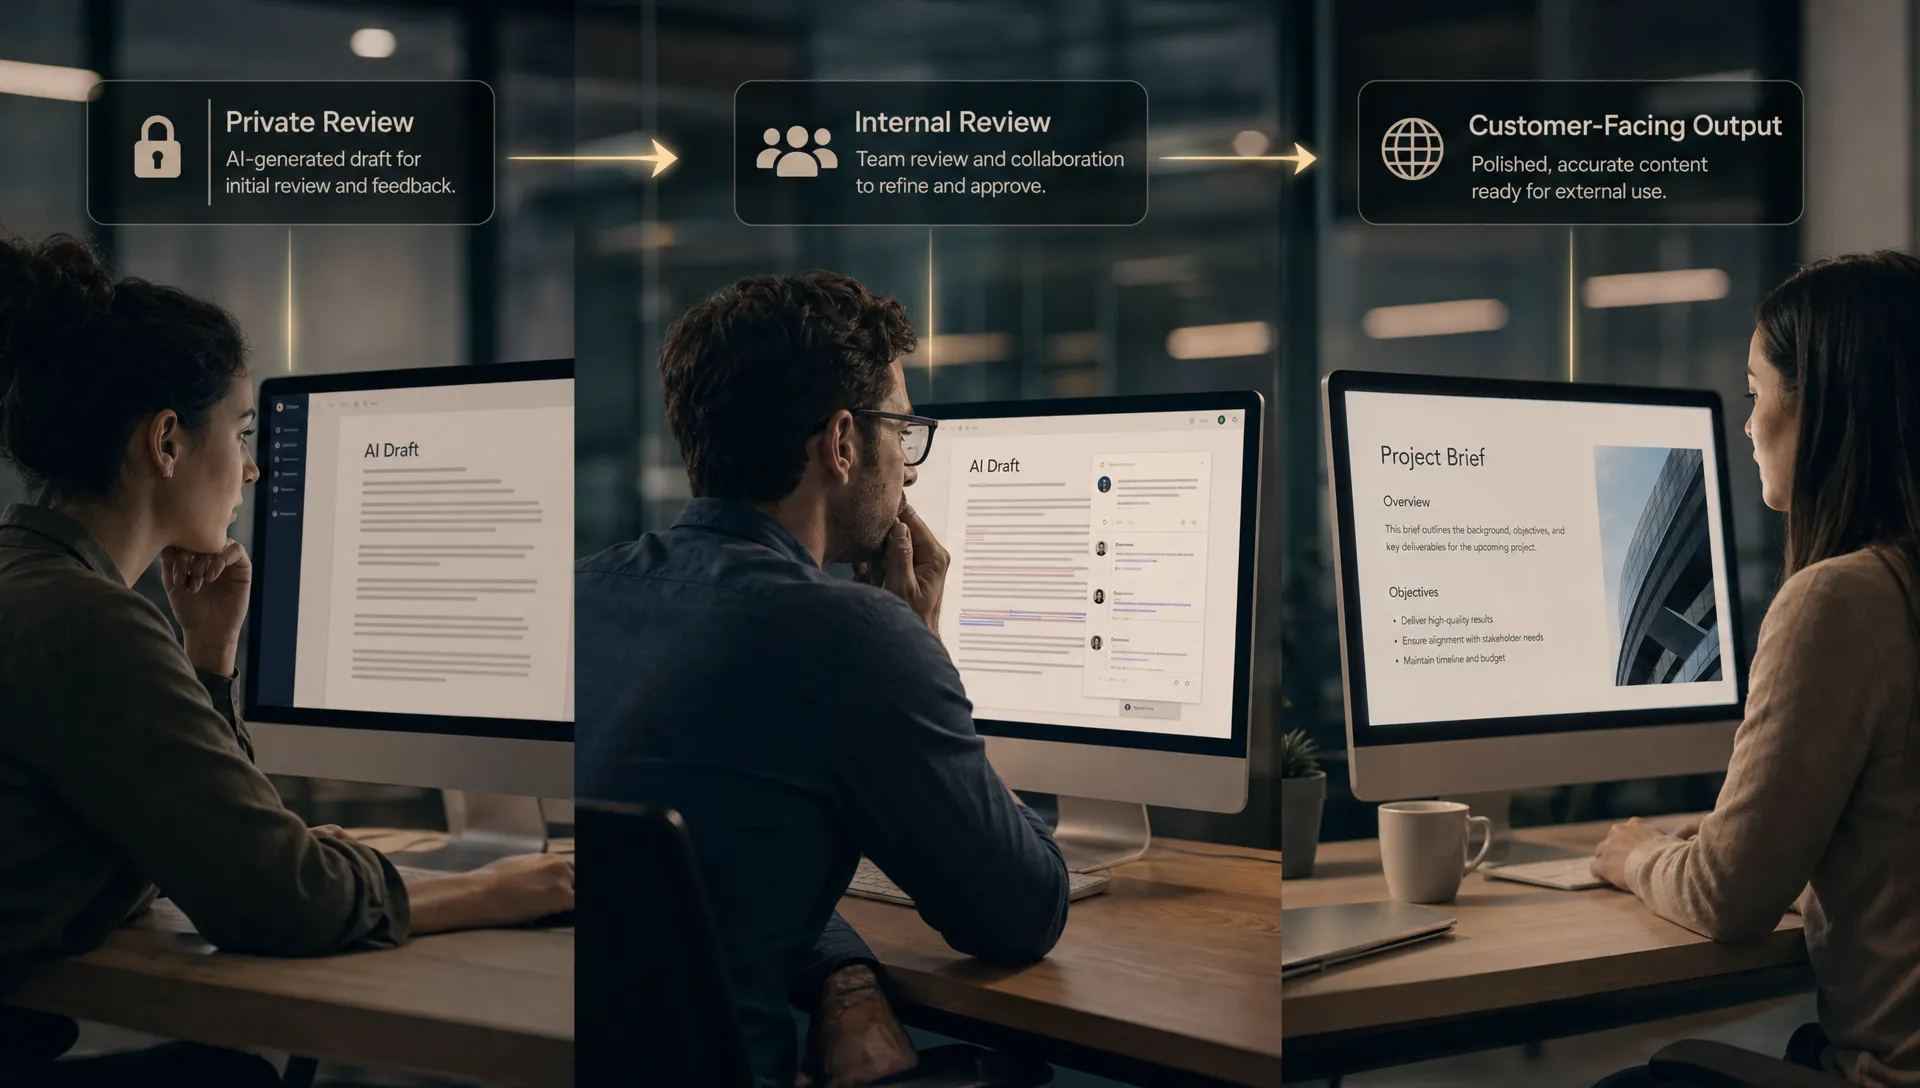
The pattern is simple. The closer the AI gets to a visible final artifact, the more the product needs to support review, control and defensibility.
Diagnose the final-audience break before changing the model
Before you tune prompts or switch models, look at where the user stops. The point of hesitation usually tells you whose judgment they are anticipating.
| Product signal | Likely diagnosis | What to inspect next |
|---|---|---|
| High draft creation, low send rate | Customer-facing risk is too high | What must be verified before send? |
| High copy rate, low in-product completion | Users trust the draft, not the workflow | Where are they doing cleanup? |
| Many regenerations with minor wording changes | Voice risk or tone mismatch | Which phrases make the output feel “not mine”? |
| Saved outputs rarely shared | Internal reputation risk | What context is missing for a reviewer? |
| Users ask for citations after generation | Evidence gap | Which claims need source support? |
| Users use AI for notes but not decisions | Accountability gap | Who owns the final call? |
This is also where “private versus shared work” becomes a practical product distinction, not a philosophical one. If your users behave differently once work leaves their own workspace, read this as an adoption break. The adjacent issue is covered in AI trust for private and shared work.
The diagnostic question is not “Do users trust AI?” That is too broad. Ask: “Who would see this output next, and what would make the user comfortable letting that happen?”
Design for the reviewer the user has in mind
Once you know who sees the final output, the product work gets more concrete. You can stop adding generic trust signals and start reducing the specific risk that blocks handoff.
For private outputs, optimize for speed and malleability
Private work needs low friction. Users are exploring, not committing. They want fast drafts, alternate angles and easy editing. Too much verification here can slow the moment down.
This is where AI onboarding strategies should teach users what the system is good at and how to steer it. Do not overload the first-run experience with compliance-style warnings if the first value is private ideation.
For internal outputs, preserve authorship
Internal sharing is often about reputation. Users worry that AI output will sound generic, miss team context or expose that they took a shortcut.
Useful product moves include editable outlines, tone controls, visible assumptions and a clear “make this sound like our team” path. The goal is not to hide AI. The goal is to help the user feel that the final artifact is still theirs.
For customer-facing outputs, support verification before send
Customer-facing AI needs a review step that fits the job. A support agent may need source snippets from the help center. A salesperson may need approved claims. A success manager may need account context and recent activity.
Do not make users verify everything from scratch. If trust requires three separate tabs, your AI feature has moved work around rather than reducing it. This is why verification friction is often misread as low interest. The user may want the output, but not the checking burden that comes with it.
For high-stakes outputs, make accountability explicit
Legal, finance, healthcare, security and enterprise admin workflows need clearer ownership. Users need to know what the AI did, what it used, what it did not check and where human approval is required.
This does not mean every AI feature needs an audit log. It means the product should match the review affordance to the audience risk. A customer email and a regulatory filing should not have the same “insert” button.
A simple product decision frame
When an AI feature stalls after generation, run the team through five questions.
- Who is the first person besides the user who might see this output?
- What would make the user look careless, wrong or off-brand to that person?
- What part of the output is hardest for the user to verify?
- Does the product help the user edit, explain or defend the output before sharing?
- Is the call to action asking for the right level of trust?
That last question is usually where the product decision lives. “Send now” may be too much. “Review sources” may be right. “Insert as draft” may be enough. “Share with notes” may unlock the internal handoff.
If you treat every output as equally final, users will create their own safety rails. They will copy into docs, rewrite manually, ask a teammate, delay sending or stop using the feature for high-stakes work.
FAQ
Why do users trust AI drafts but not final outputs? Drafts are private and reversible. Final outputs create accountability. Once another person sees the result, the user worries about accuracy, tone, reputation and whether they can defend the work.
Is this an AI product design problem or a model quality problem? It can be either, but many teams jump to model quality too fast. If users generate output but stop before sharing, the break is often review, ownership or audience risk rather than raw output quality.
Should AI products show different UI for private and shared outputs? Often, yes. Private work benefits from speed and iteration. Shared work needs review tools, source visibility, edit control or approval steps. The interface should reflect the risk of the next action.
What metric shows this trust problem most clearly? Look for gaps between generation and downstream commitment. Examples include draft-to-send rate, accepted-to-published rate, copy-to-completion rate and share rate after AI creation.
The next action
Pick one AI workflow where usage looks promising but retention is weak. Do not start by rewriting the prompt. Map the path from generation to final visibility.
Name the viewer. Name the risk. Name the missing review step.
If you want a structured way to do that across multiple adoption problems, the AI Product Adoption Deck includes diagnostic cards, action cards and workshops for turning symptoms like output abandonment into product decisions. For a faster first pass, the free AI adoption triage tool can help you identify which trust break you are actually dealing with.