The Problem of AI That Gives Different Answers to the Same Task
Diagnose the problem of AI giving different answers. Learn what must stay stable, how to test repeatability and which product decisions reduce rework.
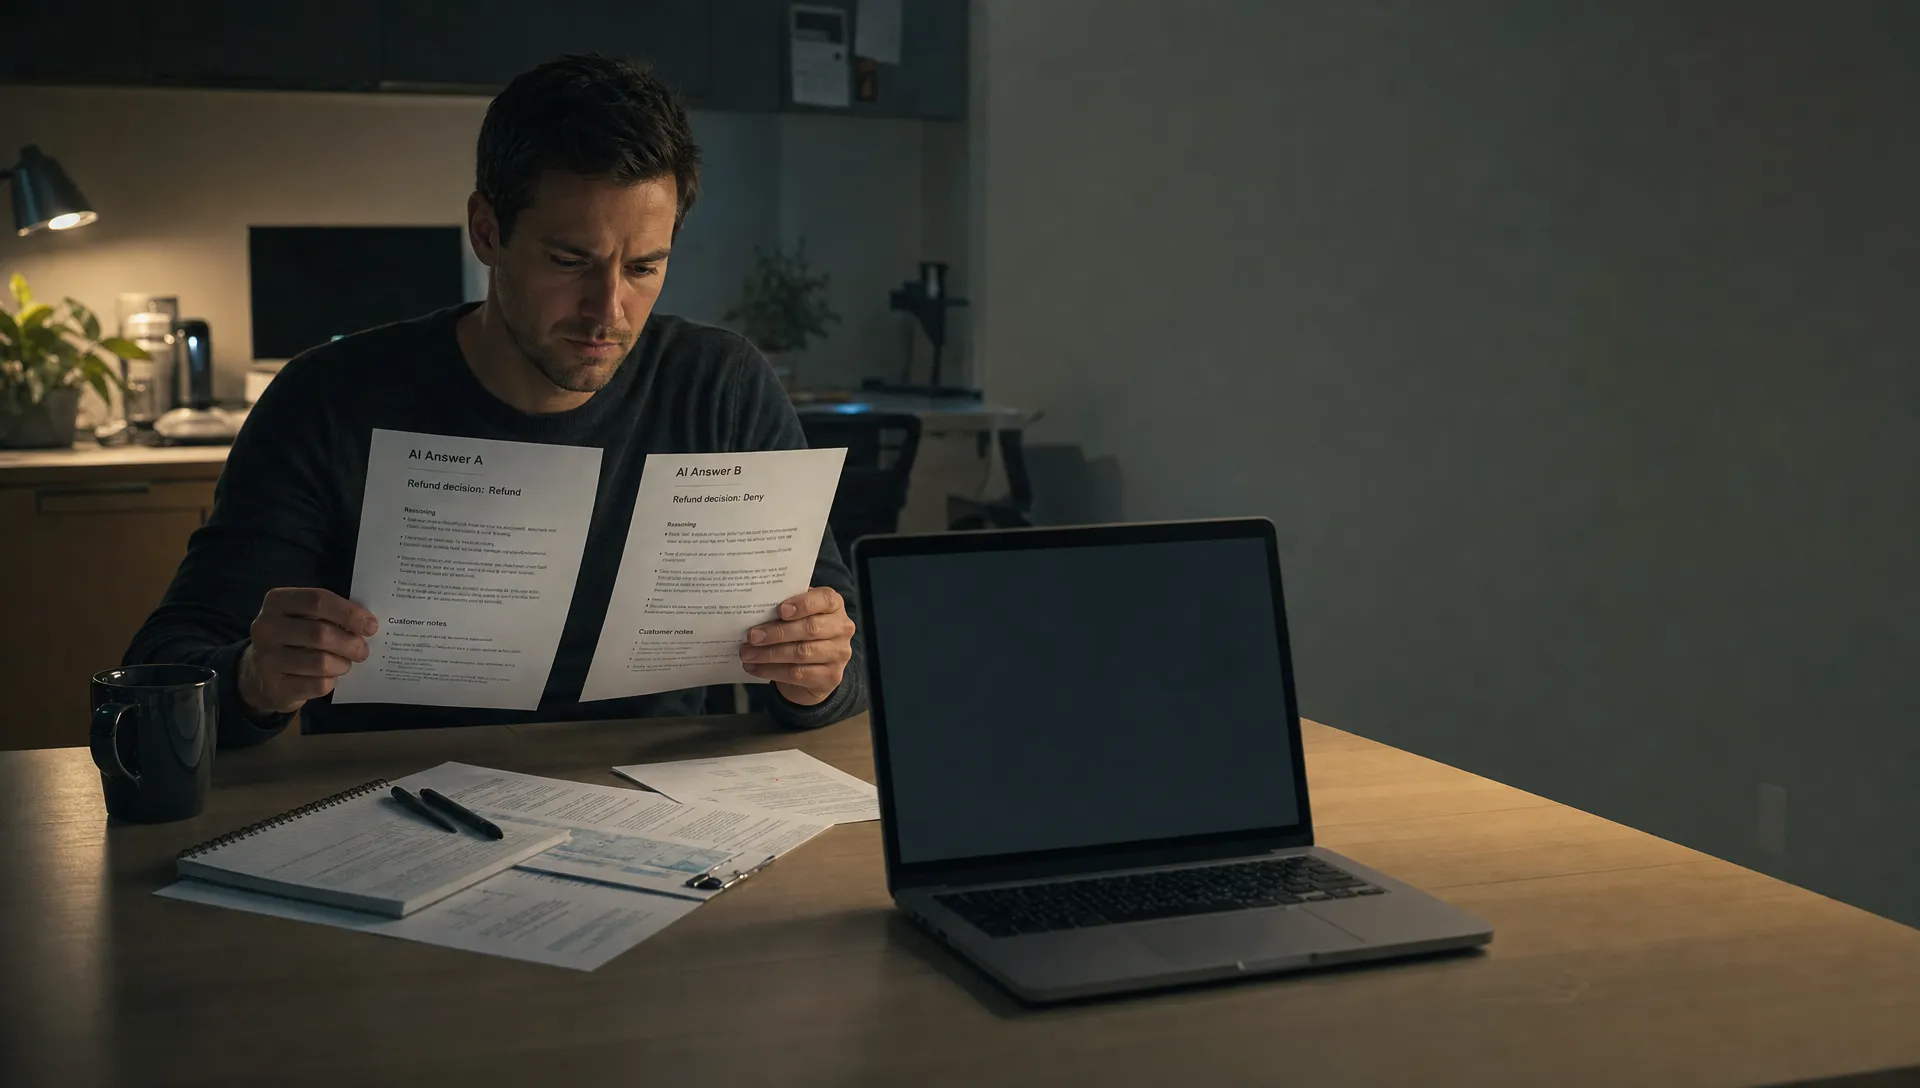
Users run the same task twice and get answers they cannot reconcile. One draft approves a refund. The next says the customer is ineligible. For a shipped product, the problem of AI giving different answers is not simply that responses vary. It is that users have to decide which response represents the product’s position.
They regenerate, compare versions and check the policy themselves. A generation metric can make that look like engagement. In practice, the feature may be creating review work instead of removing it.
Define what must stay stable
Different answers are not automatically a failure. A writing assistant can produce two useful introductions. A support assistant should not invent two different refund policies.
Before changing anything, define the task’s invariants: the facts, constraints and decisions that must survive every generation.
| Output element | Acceptable variation | Adoption-breaking variation |
|---|---|---|
| Wording | Different phrasing with the same meaning | A qualification disappears |
| Structure | Different organization that preserves required content | A required disclosure is missing |
| Facts | Different descriptions of the same supported facts | Dates, amounts or sources change |
| Decisions | The same eligibility result, explained differently | The same customer becomes eligible or ineligible |
This is a stability contract, not a demand for identical text. It tells users what they can rely on and gives your team something meaningful to test.
Keep correctness separate. An assistant that consistently applies the wrong refund policy is stable, but still unusable.
Diagnose the problem of AI before changing the model
“Same task” can hide several different conditions. Check them before treating every disagreement as model randomness.
Same visible request, different context. The user types the same words, but the product supplies different conversation history, account data or retrieved documents. The answer may be responding to a different effective input.
Same input, different generation. Even with the same supplied context, generated responses can vary. The product question is whether that variation crosses a boundary users depend on, not whether every sentence matches.
Same workflow, different system version. A prompt change, retrieval change or model update can alter behavior between visits. A user experiences this as inconsistency even if each version behaves reasonably in isolation.
Inspect the request path with your engineering partner. Compare the actual context, source versions and application configuration, not just the text in the input box. Use access-controlled traces and redact sensitive data rather than collecting everything by default.
Also check for underspecification. If “eligible customer” has no agreed definition, repeated generation is exposing a missing product rule.
Run a repeated-task test, not another demo
Make the problem of AI variability measurable with a small controlled test. Start with ten representative tasks and run each five times. These are practical starting numbers, not a statistically reliable estimate of production failure rates.
Define acceptance before generating. For a refund response, record the expected eligibility decision, policy source, permitted amount and required caveats. Do not let a persuasive answer redefine what counts as correct.
Freeze the context first. Use the same customer facts, policy snapshot and conversation state. Hold application and model versions constant where possible. This helps isolate variation in generation from changes elsewhere in the product.
Then test the normal production path. Allow retrieval and other context assembly to run as they ordinarily would. Differences between these tests can help locate the source of instability.
Compare meaning rather than exact wording. Track the share of tasks with incompatible outcomes across runs, the share of individual outputs that meet acceptance criteria and the time needed to approve or repair them.
Those measures answer different questions. A task can produce five mutually consistent answers that are all wrong. It can also produce five differently worded answers that are all usable.
Finally, observe someone completing the task. Ask what they would send or save, what they would verify and whether a second answer changes their confidence in the first.
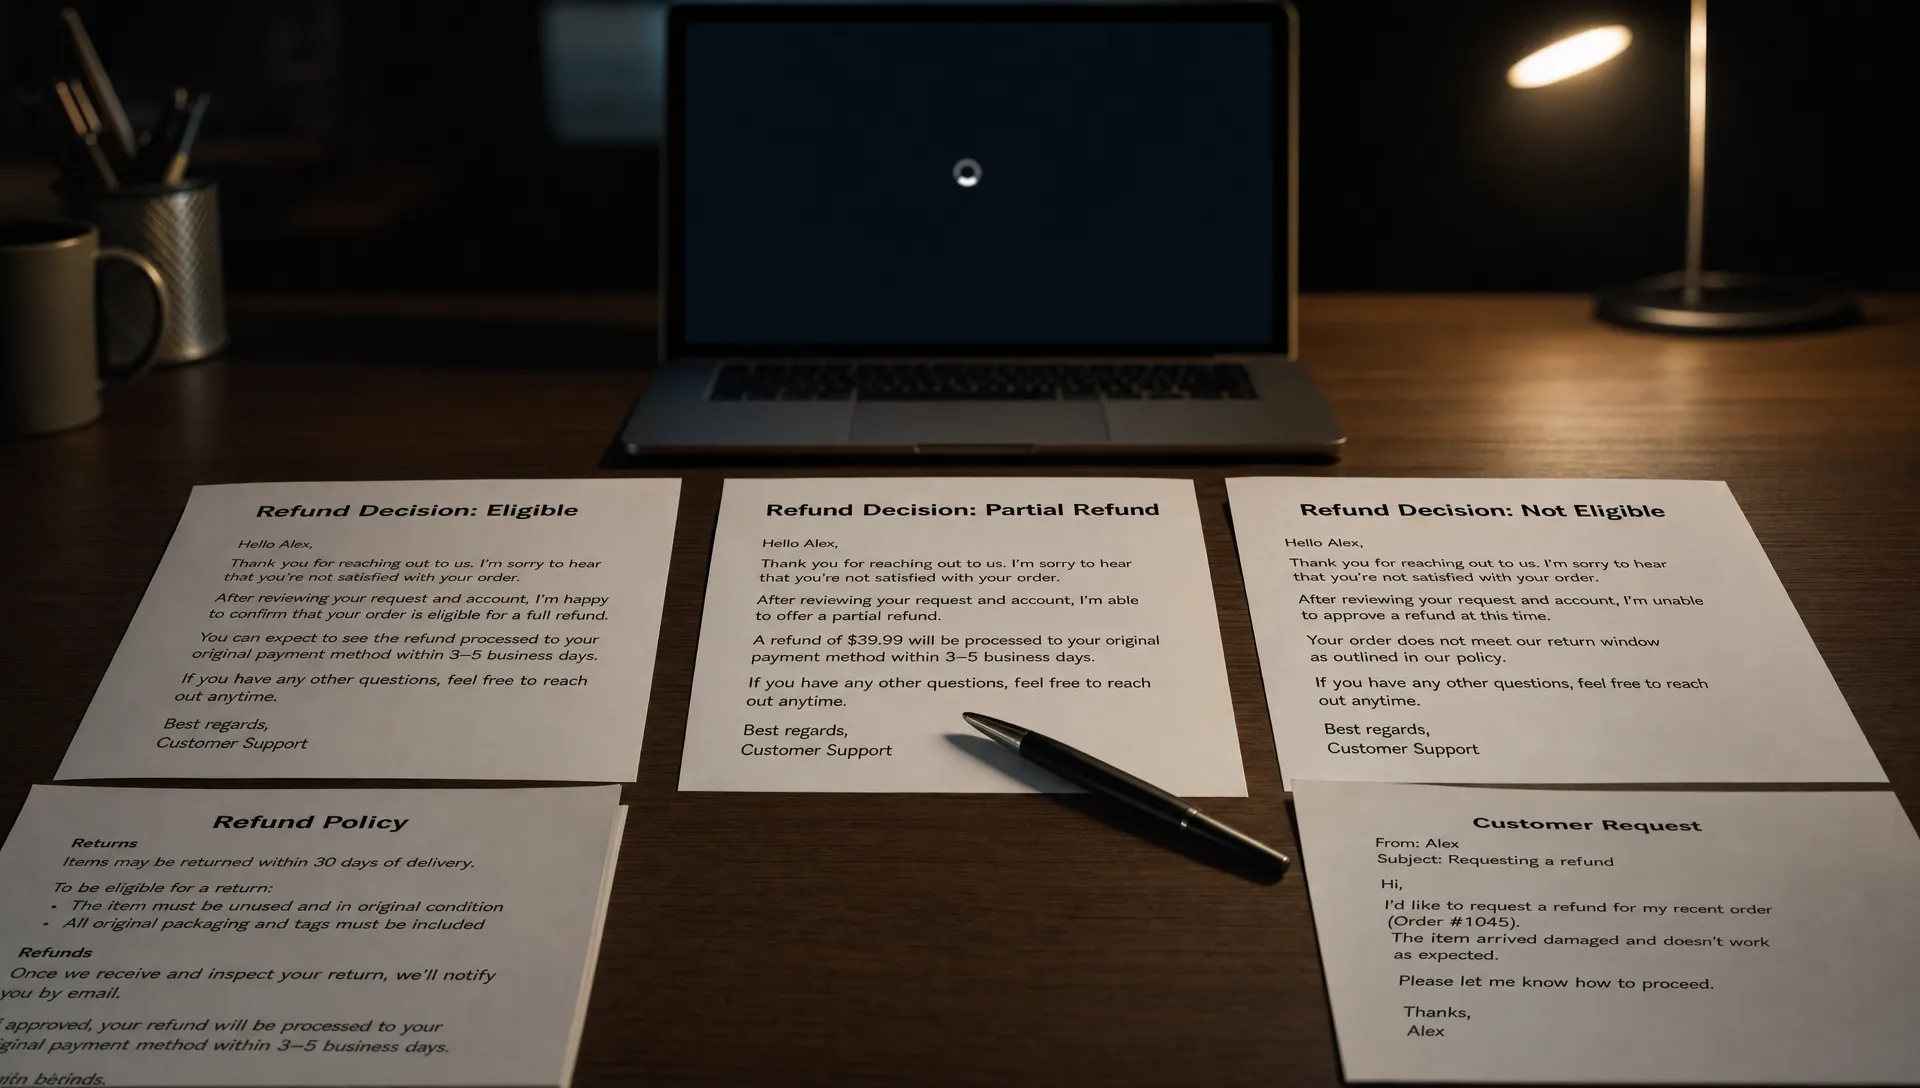
Match the response to what changed
Facts or decisions changed
Do not try to solve a policy contradiction with friendlier copy or a confidence badge.
Where eligibility follows explicit rules, calculate it outside the writing step and pass the result into drafting. Validate required facts before allowing the output to move downstream. If the decision remains uncertain, make that unresolved state visible and route it for review.
For field-level failures, the same principle applies to AI input and output mismatches in structured workflows: define what the next step requires, then validate against that contract.
Only presentation changed
Here, the problem of AI variability may be an interaction problem rather than a correctness problem.
Replace an ambiguous “Regenerate” button with actions such as “Shorten,” “Use a more formal tone” or “Show another opening.” Keep approved facts and decisions fixed while changing the requested dimension.
Preserve the user’s edits. Replacing an entire draft after someone corrects one sentence makes them repeat verification work. Offer a local revision with a visible comparison instead.
Context legitimately changed
When a policy or account fact changes, the answer may need to change too. Show the relevant source and its effective date, or make the changed input visible where permissions allow.
Do not label every difference an error. Explain why this answer differs from the earlier one. For application or model releases, rerun the repeated-task set before rollout and inspect changed decisions, not just average answer quality.
Check whether the fix reduces work
A lower regeneration count is not enough. Users might have stopped retrying because they stopped trusting the feature.
Check whether more eligible tasks reach an accepted outcome, whether review takes less time and whether users return at the next relevant task opportunity. Pair those observations with the contradiction checks from your test set.
Keep review safeguards in place for consequential outputs. Faster acceptance is not an improvement if users are simply missing more errors. The goal is dependable completion with appropriate verification, not unquestioning acceptance.
Frequently asked questions
Will lowering temperature solve the problem of AI giving different answers? It can reduce sampling variation in systems that expose that setting. It does not guarantee identical answers or correct decisions, and it does not fix changing context, conflicting sources or unclear rules.
Should we remove the regenerate button? Not necessarily. Keep it when alternatives are valuable. For tasks with a correct outcome, prioritize targeted correction and explanations over an unlimited reroll. Repeated attempts should not be the user’s method for discovering your policy.
Should every answer include a confidence score? No. An unexplained score does not establish correctness. Show relevant evidence, unresolved conditions and the review required for the task instead.
Choose one workflow and write its stability contract
Pick a recurring task where inconsistent output creates visible rework. Write down three things that must never change without new evidence. Run the repeated-task test and identify which boundary breaks first.
If you need help locating the adoption break, use the free AI adoption Triage tool. For deeper work, the AI Product Adoption Deck is a 104-card, 124-page diagnostic playbook with 12 diagnostics, 80 action cards across 10 stacks and 12 workshops with fillable deliverables.
Your next decision is specific: what may vary, what must stay fixed and what happens when the product cannot honor that distinction?