Stop Asking Users to Trust an AI Black Box
Fix AI product adoption by replacing black box UX with inspectable inputs, evidence, review paths and recovery users can trust.
Your AI feature gets tried. Users run a prompt, skim the answer, maybe regenerate once or twice. Then they copy the output somewhere else, check it manually, ask a teammate or abandon it before the real workflow starts.
That is not a curiosity problem. It is not always a model quality problem either.
It is often a black box problem.
You asked users to trust a system they cannot inspect, correct or safely contain. That might work in a demo. It breaks in production work, where the user is still accountable for the decision, the client email, the code change, the analysis or the document that ships.
For AI product adoption, trust is not a feeling you add with reassuring copy. Trust is a set of product conditions that make a user willing to move from “interesting output” to “I can use this in my work.”
What “black box” means in product terms
A black box is not just an opaque model. Most users do not need to understand transformers, embeddings or retrieval pipelines.
In product terms, a black box is any AI experience where the user cannot answer basic work questions:
- What did the system use as input?
- What did it ignore?
- What assumptions did it make?
- Which parts are safe to reuse as-is?
- What should I check before accepting this?
- What happens if I accept, publish or apply the output?
- How do I undo or correct a bad result?
When those answers are missing, the user has to build their own inspection process outside your product. That is expensive. It slows them down. It also trains them that your AI feature is a draft generator, not a workflow partner.
If you see repeat usage without acceptance, high regeneration, frequent copy-paste into other tools or low return after first success, you may already have a trust failure. This broader guide on how to tell if your AI UX has a trust problem covers those signals in more detail.
The real ask: “Trust me” is too big
A lot of AI UX asks for a large trust jump.
The product presents a confident answer. The user is expected to decide whether it is good enough. If it is wrong, incomplete or risky, the cost sits with the user.
That is a bad bargain.
The better product question is not “How do we make users trust AI?” It is “How do we reduce the amount of trust required before the user can take the next useful step?”
The National Institute of Standards and Technology frames trustworthy AI around properties like transparency, accountability, validity, reliability and safety in its AI Risk Management Framework. Product teams do not need to turn every feature into a compliance artifact. But they do need to translate those properties into UI decisions users can act on.
A user does not need a philosophy of explainability. They need the review path.
Diagnose the black box before redesigning it
Do not start by adding tooltips, confidence badges or a “Why this?” link everywhere. Start with the behavior that shows where trust is breaking.
| User behavior | Likely black box cause | Better product response |
|---|---|---|
| Users regenerate many times but accept little | They cannot tell what changed or why one answer is safer than another | Show key assumptions, meaningful differences and a comparison path |
| Users copy output into docs, spreadsheets or search | Verification is easier outside the product | Bring sources, checks or review controls into the workflow |
| Users accept only tiny suggestions | The cost of a bad large change is too high | Support partial accept, scoped edits and preview before apply |
| Users ask support where an answer came from | Provenance is missing | Show inputs, cited records, retrieved items or data boundaries |
| Users over-prompt with long instructions | The system scope is unclear | Make controllable parameters visible instead of forcing prompt gymnastics |
| Users avoid automation for high-stakes tasks | Recovery is weak | Add undo, human approval, drafts and failure states before full automation |
This table is more useful than a generic “build trust” roadmap. Each symptom points to a different fix. A team with regeneration loops needs comparison and constraint visibility. A team with low acceptance on generated changes needs preview, undo and partial control. A team with users checking every answer in Google needs evidence close to the output.
Do not replace the black box with confidence theater
A common fix is to add a confidence score.
“92 percent confident” looks precise. It rarely answers the user’s real question.
The user wants to know what to check, why the answer is plausible, where it may fail and whether accepting it will create a mess. A confidence label can help only when it is tied to inspectable evidence and clear scope. Otherwise it becomes decoration.
This is why confidence signals rarely build real trust on their own. They shift attention from the user’s review job to the system’s self-report. Most users have learned not to take that at face value.
A better pattern is to expose the reason for uncertainty. For example, “Only 2 of 12 customer records matched this claim” is more useful than “low confidence.” So is “No source found for this paragraph,” “Based only on the selected document” or “This change affects 14 files.”
Those statements give the user something to do.
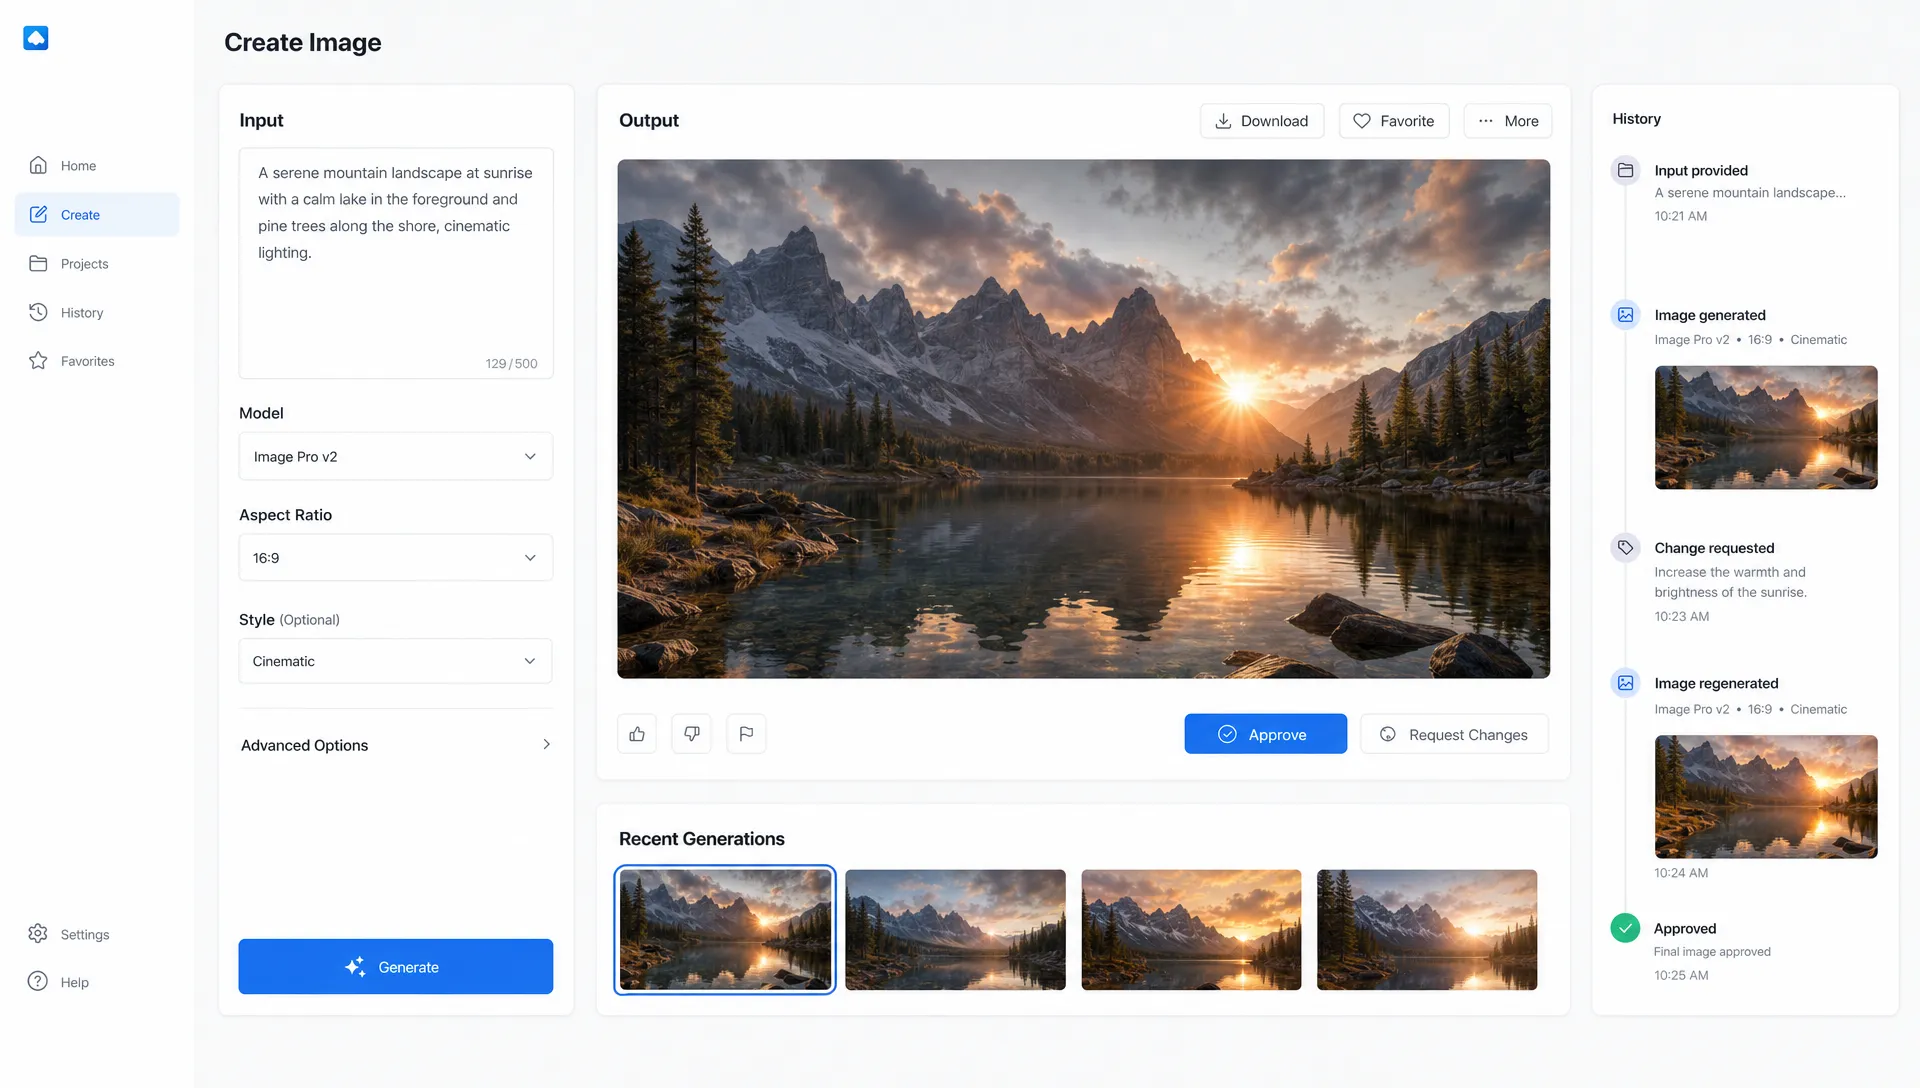
What to expose instead
You do not need to expose everything. Too much transparency creates another kind of burden. The goal is selective inspectability: show the information that changes the user’s next action.
Show the input boundary
Users need to know what the AI could see. If the feature summarizes a call, say whether it used the transcript, notes, CRM fields or prior emails. If it writes a proposal, show which documents were included. If it searches company knowledge, show the workspace or folder scope.
This prevents false trust and false rejection. Users can decide whether the output is grounded enough for the task.
Show the decision boundary
Do not blur suggestions, decisions and actions.
“Draft a response” is different from “Send the response.” “Suggest a code change” is different from “Merge the change.” “Recommend a segment” is different from “Launch the campaign.” Black box fear rises when the user cannot tell when the AI moves from advisory to operative.
Make the boundary explicit. Use draft states, previews, approvals and clear action labels.
Show evidence near the claim
Perplexity is a useful reference because it does not ask users to treat the answer as a sealed object. It puts citations near the response, making review part of the core experience. The citations are not magic. They are a review affordance.
Grammarly works similarly at a smaller scale. It suggests local changes. Users can inspect the sentence, accept or reject each edit and keep ownership of the final text.
GitHub Copilot benefits when suggestions live in the developer’s normal review environment. The user can read the diff, run tests and reject the change. The product does not need the developer to “trust AI” in the abstract. It lets them use existing verification habits.
Show what changed
For AI editing, rewriting, refactoring and workflow automation, diffs matter. Users trust deltas more than blobs.
A full rewritten document is hard to inspect. A section-level diff is easier. A proposed CRM update with highlighted changed fields is easier. A code suggestion with a visible patch is easier.
If the user has to compare manually, your product has pushed verification cost onto them.
Show recovery before asking for commitment
Undo is not just a safety feature. It is a trust feature.
Users are more willing to try AI when they know mistakes are containable. That means draft modes, version history, reversible changes, clear rejection controls and a path to correct the system when it goes wrong.
Recovery also affects retention. If the first bad output leaves the user cleaning up a mess, they learn to avoid the feature. If the first bad output is easy to fix, they keep experimenting.
Onboarding should teach the review job
Many AI onboarding flows teach prompting. That is often the wrong lesson.
Prompting helps when the user already trusts the workflow enough to invest effort. Early on, users need to know how to judge the output, where it came from and what the product will or will not do on their behalf.
Good AI onboarding strategies make the review contract obvious:
- “We will draft, you approve before anything is sent.”
- “We used these 4 sources.”
- “Check these 3 fields before applying.”
- “You can accept individual changes.”
- “Undo is available for all AI actions in this workspace.”
That is product onboarding, not prompt education. It tells users how to safely integrate the AI feature into real work.
A simple decision frame for your next release
Before adding another model improvement, ask where your current experience demands blind trust.
| Product question | If the answer is no, consider |
|---|---|
| Can users see what input the AI used? | Add source scope, selected records or visible context |
| Can users inspect the basis for important claims? | Add citations, evidence panels or linked records |
| Can users accept part of the output? | Add granular accept, edit and reject controls |
| Can users preview impact before applying? | Add diffs, simulations or affected item counts |
| Can users recover from a bad result quickly? | Add undo, versioning, draft mode or approval steps |
The point is not to make every AI feature fully explain itself. The point is to stop asking users to take an unpriced risk.
AI product adoption improves when the product carries more of the verification burden. Not all of it. Enough that the user can keep moving without leaving the workflow.
Frequently Asked Questions
What is an AI black box in product design? An AI black box is an experience where users cannot see enough context to judge the output. They may not know what inputs were used, what assumptions were made, what changed or how to recover from an error.
Do users need full explainability to trust an AI feature? No. Most users need practical inspectability, not a technical explanation. They need to know what to check, what evidence supports the output and what happens if they accept it.
Are confidence scores useful for AI product adoption? Sometimes, but only when paired with evidence, scope and next actions. A percentage without context often creates false precision and does not reduce the user’s review burden.
What is the fastest way to reduce black box anxiety? Add a visible review path. Show inputs, evidence, changes and recovery controls close to the AI output. This usually helps more than adding more generic reassurance copy.
Next action
Pick one important AI workflow in your product. Watch where users pause, regenerate, copy output elsewhere or avoid applying the result. Then name the missing review affordance.
If you want a structured way to do that across activation, trust, output quality and retention, the AI Product Adoption Deck includes diagnostic cards, action cards and workshops for turning these symptoms into product decisions.