How to Set Clear Expectations for Unreliable AI Tasks
Set expectations for unreliable AI tasks so users know what to verify, when to trust output and where human review belongs.
Your AI feature is not failing only because the model gets things wrong. It is failing because users cannot tell what kind of wrong to expect. For unreliable AI tasks, vague promises like “generate a complete plan” create an adoption trap: the user expects finished work, gets a near miss, then quietly stops using the feature. That is an AI product adoption problem, not just a model quality problem.
The fix is not to apologize more often. It is to set the right expectation before the user invests time, shares data or puts the output into a real workflow.
The adoption break: users read uncertainty as incompetence
Most product teams describe AI features by the best case. Summarize this doc. Write this email. Find the answer. Build a roadmap. That framing works in a demo because everyone understands the scene is controlled. It breaks in production because real users bring messy context, incomplete inputs and higher stakes.
When the output is imperfect, users do not always think, “This task is probabilistic.” They think, “This product is unreliable.” After that, every future result gets reviewed with more suspicion. The user may still try the feature, but reuse drops because the mental cost is too high.
Unreliable does not mean useless. A writing assistant can be useful if users expect a draft. A research assistant can be useful if users expect leads to verify. A coding assistant can be useful if users expect suggestions to test. The problem starts when the product sells a task as complete work but delivers something that still needs judgment.
Why unreliable AI tasks need explicit expectation setting
Unreliable AI tasks usually fail in one of four ways. The model may miss context. It may produce a plausible answer with an unsupported claim. It may over-apply a pattern from training data. Or it may do the right thing for the wrong user goal.
Those are different failures. They need different product responses.
If users do not know which failure mode is likely, they cannot decide how to use the output. They either overtrust it and create downstream risk, or undertrust it and abandon the workflow. Both outcomes hurt adoption.
A useful expectation tells the user three things:
- What the AI is likely to be good at for this task
- What it will not know unless the user provides it
- What the user still owns before the output is used
NIST’s AI Risk Management Framework separates reliability, validity, safety and accountability for a reason. In product terms, users need to know what job the system can safely own and where human review is still part of the workflow.
Set expectations at the task level, not the feature level
Generic labels like “AI assistant” or “smart suggestions” do not help users calibrate trust. They describe a capability, not a task boundary. The same system can be low risk in one task and high risk in another.
For example, Notion AI drafting a first version of meeting notes is a different expectation from Notion AI deciding the action items for a cross-functional launch. GitHub Copilot suggesting a code completion is different from a system automatically deploying a change. Grammarly suggesting a rewrite is different from rewriting legal language without review.
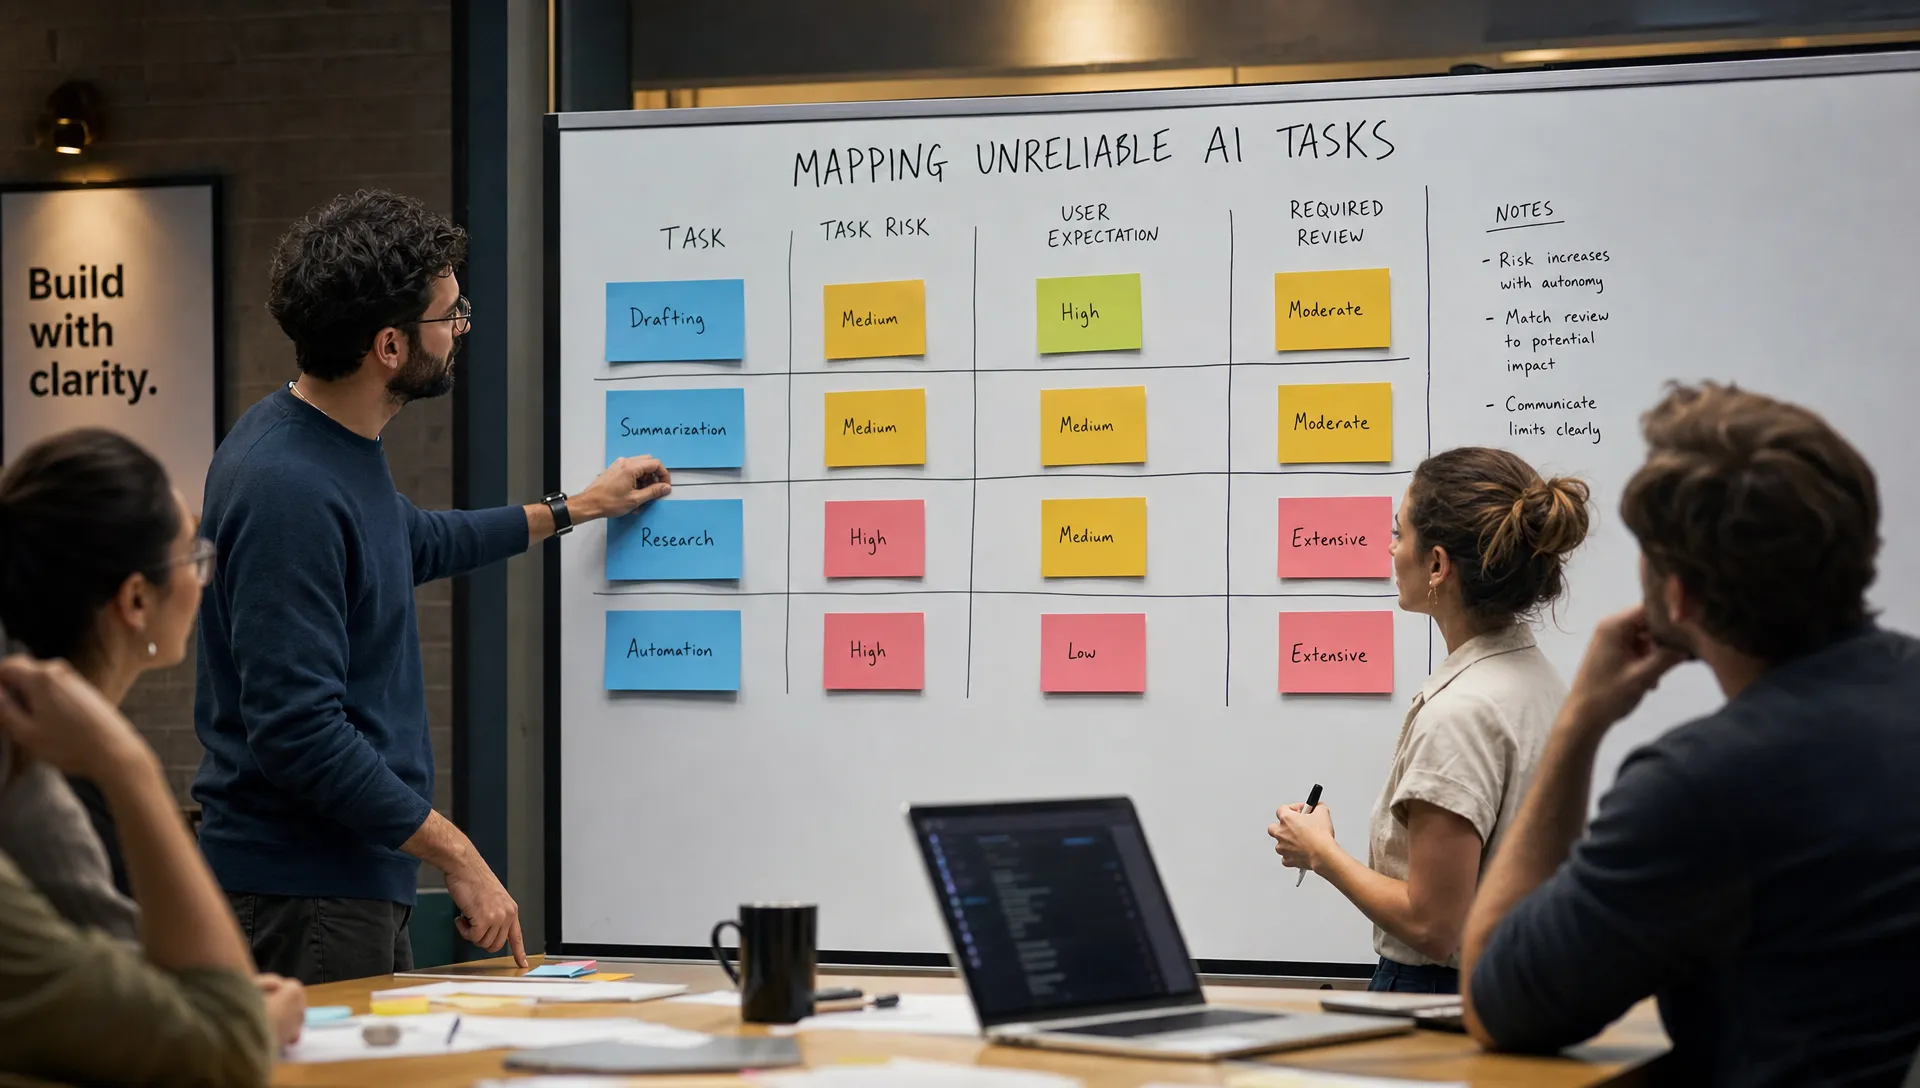
Treat each task as its own promise. A clear task expectation should define the input, output, review burden and failure pattern.
| Task type | Better expectation | Risky expectation |
|---|---|---|
| Drafting | Creates a starting point you should edit | Writes the final version |
| Summarization | Condenses visible source material | Captures every nuance and implication |
| Research | Finds candidate answers and sources | Gives a complete verified answer |
| Classification | Suggests a likely label | Decides the label without review |
| Recommendation | Ranks options using stated criteria | Knows what the user should do |
| Automation | Prepares an action for approval | Acts correctly without confirmation |
This is where many AI onboarding strategies go wrong. They teach users where the button is, but not how to judge the result. Good onboarding for unreliable AI tasks does not promise magic. It teaches the operating envelope.
Diagnose which expectation broke
Before rewriting empty states or adding confidence badges, identify the specific expectation gap. Low adoption can come from several different breaks.
| User behavior | Likely expectation break | Product response |
|---|---|---|
| Users regenerate repeatedly | They expected the first output to be closer to finished | Narrow the task, add examples or ask for missing context upfront |
| Users copy output elsewhere to check it | They do not know what evidence supports the result | Add sources, citations, diffs or traceable reasoning steps |
| Users edit almost everything | The product framed a draft as final | Reposition the feature as a starting point and support partial acceptance |
| Users try once but do not return | The task looked useful but required too much verification | Reduce scope or integrate review into the workflow |
| Users accept risky output too quickly | The product hid uncertainty or review responsibility | Add approval gates and make risk visible before action |
| Users avoid high value use cases | The boundary of safe use is unclear | Show safe and unsafe examples during setup |
If the main issue is verification, expectation copy alone will not fix it. Users need a way to inspect the output. The pattern is covered more directly in AI trust drops when users cannot check the output.
Make uncertainty operational, not decorative
Many AI products try to solve trust with a confidence score. That can help in narrow classification tasks where the number is calibrated and tied to a decision. In most product workflows, “82 percent confident” is not actionable.
Use labels that change what the user does next.
“Needs review” is better than a vague score if the user must inspect the output. “Based only on this document” is better if the risk is missing context. “No source found” is better if the issue is evidence. “Ready to apply after approval” is better if the next step changes user data, sends a message or updates a record.
The point is not to make the AI look cautious. The point is to make the workflow safer and faster. If uncertainty does not change the next action, it is UI decoration.
Place the expectation before the user invests effort
Expectation setting works best before commitment. If the user learns the limitation after reading a long output, checking facts and editing paragraphs, the product has already created waste.
Put the expectation near the moment of intent:
- In the prompt field, show what kind of input improves the result
- Before generation, state what the system can and cannot use as context
- During generation, show which sources or objects are being considered
- In the result, separate generated content from evidence and assumptions
- Before apply or publish, make the user approve the risky part
This is especially important for products that act inside existing workflows. Users are busy. They do not want a tutorial every time, but they do need a small, well placed signal that tells them how much responsibility the AI is taking.
If your AI can change state, send messages, update records or affect customers, this becomes a boundary problem too. A related breakdown is covered in AI and trust break when users cannot set a safe boundary.
Match the expectation to task risk
Do not use one trust model across every feature. A low risk creative task can tolerate surprise. A high risk operational task cannot.
| Task risk | Example | Expectation to set | Product control |
|---|---|---|---|
| Low | Brainstorm headline options | Expect variation and taste differences | Easy regenerate and edit |
| Medium | Summarize customer calls | Expect gaps if source data is incomplete | Source links and editable summary |
| High | Recommend account action | Expect decision support, not autopilot | Criteria, evidence and approval gate |
| Critical | Send customer communication | Expect human ownership before send | Preview, review and clear accountability |
This is why “make the AI more trustworthy” is too broad. Trust has to be calibrated by task risk. If you need a deeper decision frame, use how to calibrate AI trust by task risk as a companion piece.
Instrument the expectation gap
You cannot manage this only through user interviews. Add adoption metrics that show whether users understood the task promise.
Track acceptance rate, but do not stop there. Look at regeneration rate, edit depth, time to first useful output, undo rate, discard rate and repeat use by task type. For risky workflows, track how often users open evidence, expand sources, change assumptions or cancel before applying.
The pattern matters more than any single metric. High generation with low reuse usually means curiosity without trust. High acceptance with frequent downstream correction can mean overtrust. Heavy editing with good retention may mean the product is useful as a draft tool, even if the original success metric looked weak.
If you are not sure which adoption problem you have, the free AI product triage tool can help sort the symptom before you pick a fix.
A practical decision frame for product teams
Before shipping or changing an unreliable AI task, answer five questions in the product spec:
- What task are we promising, in the user’s words?
- What inputs does the AI need to do that task well?
- What common failure should the user expect?
- What part of the output must the user verify?
- What product control prevents overtrust or wasted review?
If the team cannot answer those questions, the feature is not ready for stronger claims. It may still be useful, but the promise needs to shrink until the workflow is honest.
For teams that want to turn this into a repeatable review process, the AI Product Adoption Deck includes diagnostics, action cards and workshop templates for mapping adoption symptoms to concrete product changes.
Frequently Asked Questions
What makes an AI task unreliable? An AI task is unreliable when output quality varies based on context, input quality, ambiguity or hidden assumptions. The task can still be valuable if users know how to review and apply the output.
Should we tell users the AI may be wrong? Yes, but that warning is too generic by itself. Tell users what kind of error is likely, what they should check and what the AI did or did not use as evidence.
Are confidence scores a good way to set expectations? Only when the score is calibrated and tied to a clear action. For many AI product workflows, labels like “source checked,” “missing context” or “needs approval” are more useful.
Where should expectation setting appear in the UI? Put it before the user invests effort, ideally near the prompt, setup, preview or approval step. Result level caveats help, but they arrive late if the user already spent time reviewing the wrong kind of output.
How do we know if expectations are too high? Watch for repeated regeneration, heavy outside verification, high discard rates, low repeat use or users saying the feature is “almost useful.” Those are signals that the product promise is larger than the dependable task.