How AI Works When Users Need to Check Its Output
Make “ai how it works” useful at review time. Diagnose source, inference and action confusion so users can check output before using it.
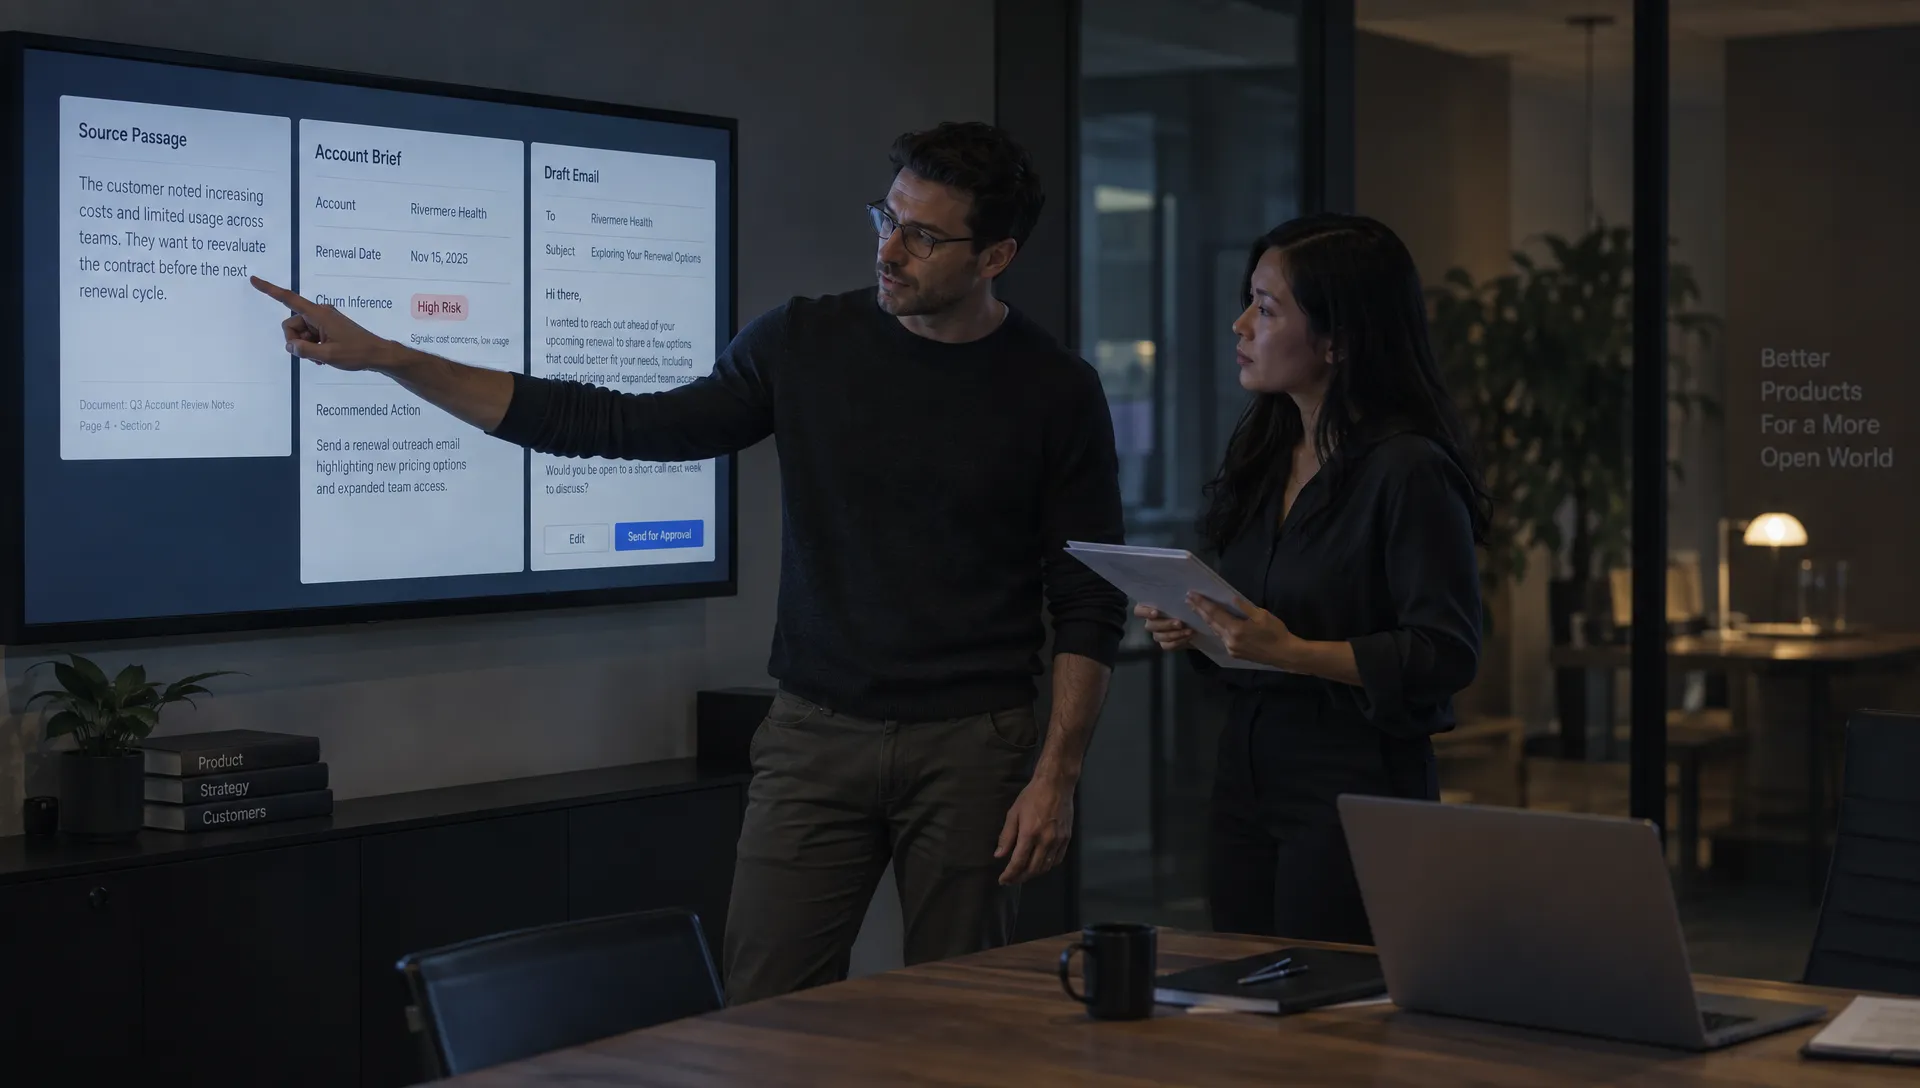
Users open the result, check three facts elsewhere, then write their own version. Your “ai how it works” explanation may describe the model, but it does not tell them which statements came from records, which were inferred or whether anything actually happened.
That is a specific adoption break: users cannot map the output to the right kind of check. They treat a retrieved date, an inferred recommendation and a proposed action as equally uncertain. Or they trust all three because the answer sounds confident.
Neither response gives you reliable adoption. One creates unnecessary review work. The other hides mistakes until someone uses the result.
The product needs to explain its operating boundaries where users make decisions. Not a lesson on neural networks. A clear account of what produced this result, what supports it and what remains the user's responsibility.
What an “ai how it works” explanation needs to establish
An AI-generated response can contain several different operations. Your application might retrieve a customer record, calculate a total, generate a summary and propose an email. The interface then presents everything as one polished answer.
That presentation removes distinctions users need for review. A renewal date needs a source check. A total needs an input and calculation check. A recommendation needs a judgment call. An email needs an approval and delivery-state check.
The useful mental model is not “the AI knows this.” It is “this part came from here, this part was derived and this part has not happened yet.”
Your “ai how it works” guidance should establish those distinctions before asking users to approve the result. Otherwise, approval becomes a vague endorsement of the entire response rather than a decision about specific claims and actions.
Explain three boundaries in the output
The evidence boundary: retrieved does not mean verified
A source link tells users where to look. It does not establish that the source supports the claim, is current or belongs to the right account.
For consequential facts, connect the claim to the relevant record or passage. Show when the underlying information was last updated if freshness matters. Keep missing information visibly missing rather than allowing generated prose to fill the gap.
This is the distinction between AI transparency and useful proof: users need evidence that resolves a decision, not a badge saying sources were involved.
The inference boundary: generated does not mean observed
“The customer mentioned budget pressure” and “the customer is likely to churn” are different claims. The first may be supported by a conversation. The second is an inference.
A useful “ai how it works” explanation makes that difference visible beside the claim. Label a recommendation as an inference and show the observations it relies on. Let users challenge those observations without regenerating the entire answer.
If your application calculates a value, expose the relevant inputs and calculation. Do not present generated arithmetic as equivalent to a result from a defined calculation.
The action boundary: requested does not mean completed
A model can propose an action or request a tool call. The application must execute that request and handle the result. OpenAI's function-calling documentation describes this separation between a model's tool request and application-side execution.
That distinction belongs in the interface. “Draft prepared,” “awaiting approval” and “sent” are different states. Display completion only when the underlying system confirms it. A conversational “done” is not sufficient evidence that an email was delivered or a record changed.
Diagnose the mistaken assumption before changing the copy
Watch users review a real output. Ask them to identify what came from a source, what the system inferred and what changed outside the conversation.
Their answers reveal whether the explanation is missing, misplaced or contradicted by the interface.
| Observed behavior | Possible mistaken assumption | Product response to test |
|---|---|---|
| User checks every field against the original record | All content appears generated | Distinguish record-backed fields from generated interpretation |
| User accepts a recommendation as a recorded fact | Fluent prose appears authoritative | Label the inference and expose its supporting observations |
| User thinks a drafted message was sent | Conversational wording implies execution | Show explicit approval and delivery states |
| User approves without opening evidence | Approval appears to mean accepting the wording | State which consequential claims require review |
These are hypotheses, not diagnoses based on telemetry alone. A user might reopen a record because your data is stale, not because they misunderstand AI.
Evaluate “ai how it works” guidance by whether it corrects the observed assumption. Adding an explanation panel will not fix a main interface that still presents every statement as equally established.
Worked example: an AI-generated account brief
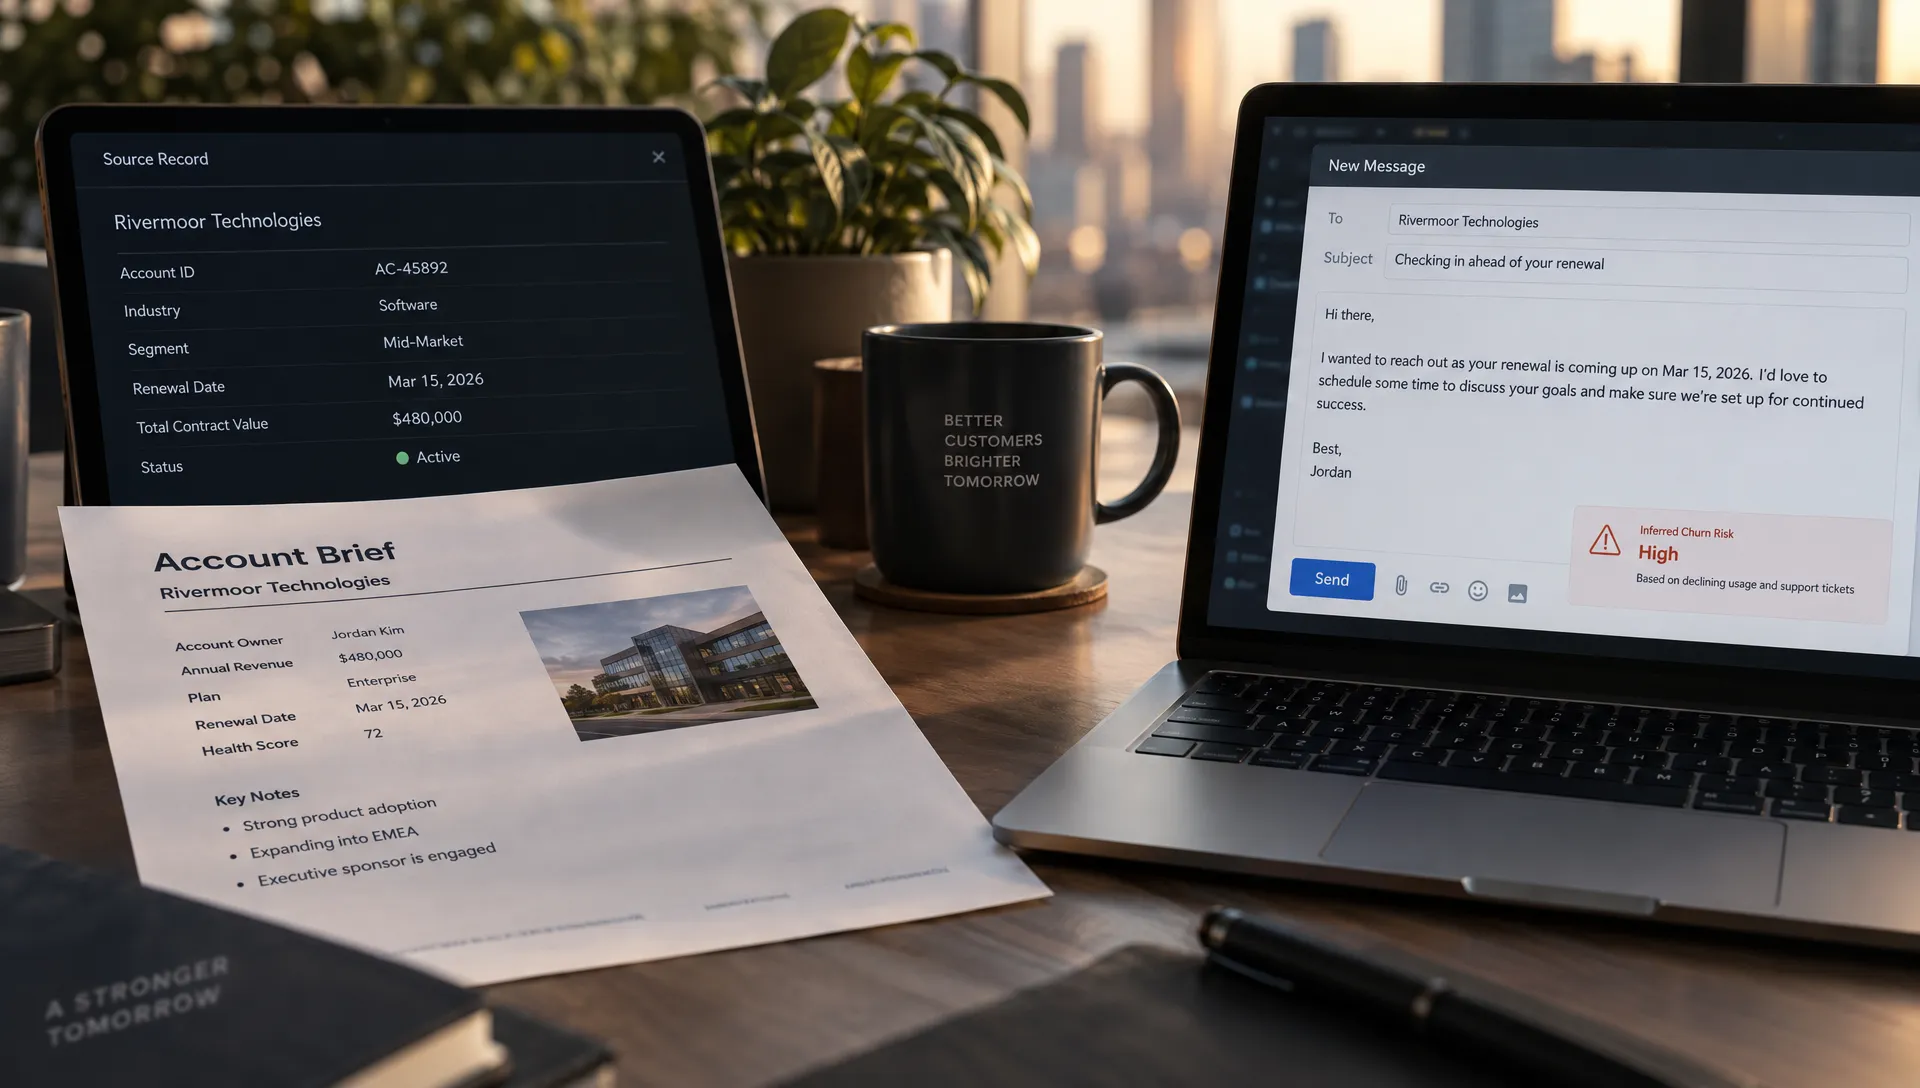
Consider a hypothetical SaaS feature that prepares an account brief before a renewal call. It produces three lines:
- Renewal date: November 15, taken from the account record.
- Risk assessment: Possible churn risk, inferred from two recent support conversations.
- Follow-up: Email drafted, not sent.
The review experience should preserve those differences. The date links to its record. The risk assessment links to the relevant conversation passages and remains visibly interpretive. The email opens as an editable draft with a separate send action.
Suppose the user rejects the churn assessment because the support conversations concern an already-resolved issue. That correction should change the assessment without altering the renewal date or sending the email.
A single “Looks good” button obscures all of this. It leaves the user guessing whether they approved the facts, accepted the interpretation or authorized an action.
Test comprehension through behavior, not reassurance
Do not ask only whether the explanation made users feel more confident. Confidence can rise without review becoming more accurate.
Test your “ai how it works” explanation with a controlled prototype containing a stale source, an unsupported inference or a draft that has not been sent. Keep these tests out of live consequential workflows.
Ask users to decide what they would use, what they would check and what they would reject. Compare their decisions before and after the interface change.
Track whether users catch the seeded issue, distinguish draft from completed action and preserve valid content while correcting the faulty part. Measure review time alongside error detection, not instead of it.
Faster approval is not automatically better review. Your change should remove redundant checks without removing the checks that protect the user's next decision.
Frequently asked questions
Should we show the model's reasoning? Do not treat a generated rationale as an audit trail. Show the sources, inputs, calculations and recorded tool outcomes that users can inspect. An explanation of an answer is not proof of how it was produced.
Do confidence scores help users check output? Only if the score has a defined, validated meaning for the task. An uncalibrated percentage can encourage misplaced certainty. Evidence and clear output states are often more actionable.
Should every AI output require approval? No. Match review to the consequence of error and whether the action is reversible. An editable private draft needs a different review contract from an externally sent message or a changed customer record.
Make one output reviewable this week
Choose a frequently abandoned output. Mark every consequential element as sourced, calculated, inferred or awaiting action. Then watch a user review it without coaching.
Put the “ai how it works” explanation beside the decision it supports, not only in onboarding.
If you need to diagnose the wider adoption break, use the free Triage tool. For deeper work, the AI Product Adoption Deck provides 12 diagnostics, 80 action cards and 12 workshops with fillable deliverable templates.