An AI Adoption Framework for Finding the First Broken Step
Use an AI adoption framework to find the first broken step, separate symptoms from causes and choose one measurable product fix.
Users generate an answer, leave it untouched and never return. Your dashboard calls that activation because the model responded. Your users may not have completed anything. An AI adoption framework should separate those two outcomes, then identify the earliest handoff that prevents useful work. Otherwise, you can spend a quarter improving output quality when the actual break is that nobody knows whether the result is safe to use.
The goal is not to score every part of your AI feature. It is to find the first failure you can explain well enough to test.
Start with one eligible task
“People aren’t using AI” is too broad to diagnose. Pick one user group, one recurring task and one intended outcome.
For an account-brief feature, that might be: account executives preparing for an upcoming customer call, using account records to produce a brief they can use during the meeting. Opening the assistant is not the outcome. Neither is generating a summary.
Define eligibility before calculating adoption. A salesperson without an upcoming call has no immediate reason to create a brief. Including that person in your activation denominator makes lack of demand look like product friction.
Also name the current alternative. If users already prepare from a familiar account page, your feature must save enough effort to justify checking its work. Compare against that workflow, not against doing everything manually from scratch.
An AI adoption framework built around handoffs
Follow the task through observable transitions. Each transition asks the user to make a different commitment: supply context, evaluate an answer, accept responsibility or bring the result into real work.
| Handoff | Evidence to inspect | Possible break | Response worth testing |
|---|---|---|---|
| Eligible task → start | Entry-point exposure and task starts | Users cannot connect the feature to their immediate task | Put a specific task entry point inside the existing workflow |
| Start → usable input | Abandoned prompts and missing context | Users do not know what to provide | Offer a bounded input structure or relevant context selection |
| Output → evaluation | Source inspection and observed checking behavior | Users cannot judge whether the answer is dependable | Make supporting evidence inspectable |
| Evaluation → workable result | Edits, retries and discarded drafts | Correcting the answer costs more than replacing it | Let users repair a specific part without restarting |
| Workable result → application | Insertion, export or downstream task completion | The answer is stranded outside the workflow | Reduce the transfer work |
| Application → next eligible use | Return on the next relevant task | Previous value does not justify another attempt | Investigate remembered effort, failure and task cues |
These are diagnostic handoffs, not mandatory screens. Some tasks need no editing. Others require review before anything can be applied. Follow the actual route users take, including branches and recovery paths.
Use conditional rates, not one adoption percentage
An AI adoption framework becomes useful when every rate has a clear denominator. “Thirty percent adopted” tells you little unless you know who had a task, who received an output and who had another opportunity to return.
Consider this illustrative cohort, not a benchmark:
- 120 users have a relevant task and see the entry point; 100 start.
- 90 of those starters receive an output.
- 30 of those 90 apply the output to their work.
- 18 of those 30 encounter another eligible task during observation; 12 use the feature again.
Output application is 30 out of 90. Opportunity-adjusted return is 12 out of 18, not 12 out of 120. Those rates describe different problems.
The application handoff deserves investigation, but the numbers do not explain why it failed. Users might distrust the answer, find it irrelevant or struggle to transfer it. Instrumentation locates the transition. Observation and task evidence explain it.
Keep a shared attempt identifier across these events. Otherwise, repeated generations can inflate activity while hiding how many tasks actually reached completion. Collect only the content and context needed for diagnosis, with appropriate access controls.
Choose the earliest break supported by evidence
The first large drop is a place to investigate, not an automatic diagnosis. A user who never starts may be making a sensible choice. A user who accepts every output may be taking an unsafe shortcut.
Use the AI adoption framework to distinguish a blocked handoff from an appropriate exit. Review attempts from the same task and user segment, including successes, abandoned attempts and recoveries.
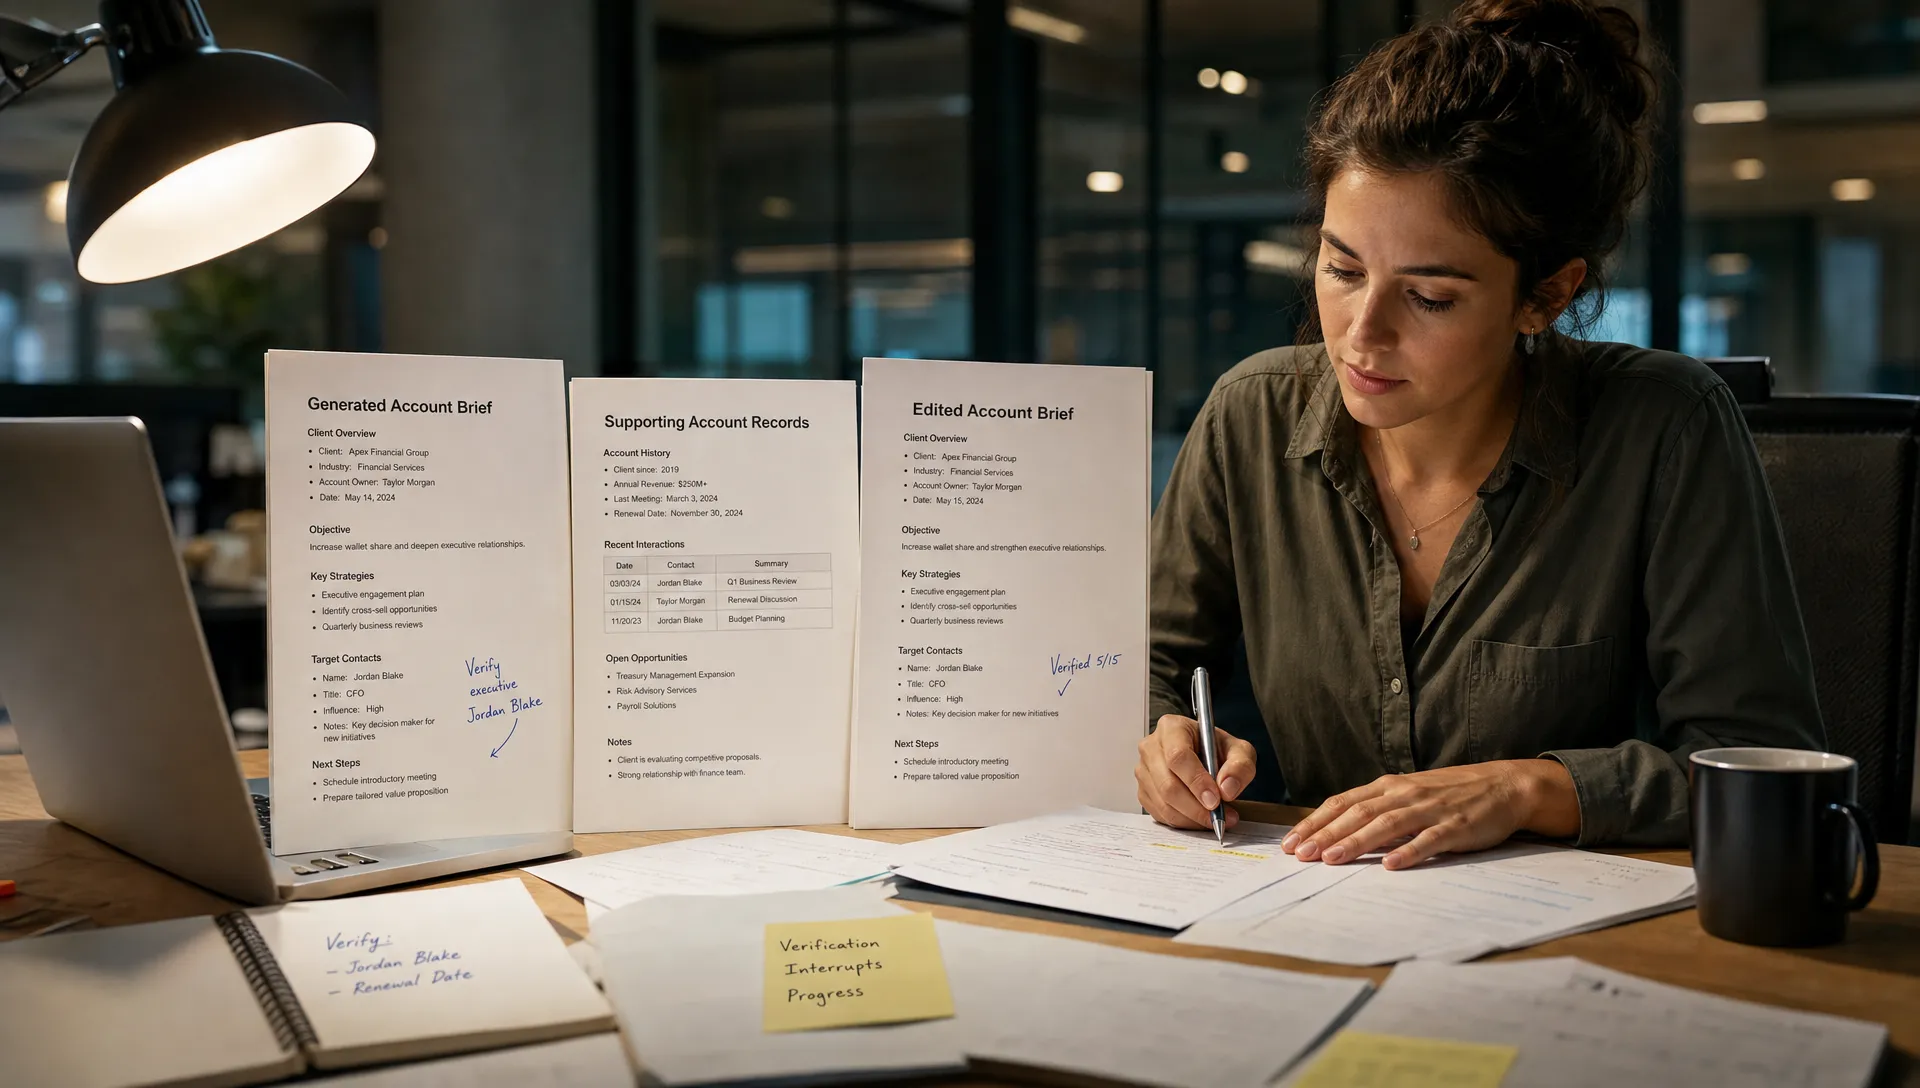
In the illustrative account-brief case, suppose observation shows that users understand the entry point and receive relevant drafts. They then reopen account records to verify every claim. Some finish preparation there and abandon the draft. That supports a verification-cost diagnosis, not simply “low trust.”
Write the finding narrowly: “Users cannot connect claims in the brief to supporting records without rebuilding the research.” That statement suggests a product change. “Users need more confidence” does not.
“First” means the earliest supported failure that prevents value on this route. It does not mean every upstream rate must reach an arbitrary target before you investigate downstream behavior.
Test one handoff without moving the failure
For the verification problem, test claim-level access to the underlying records. Do not simultaneously rewrite onboarding, change the entry point and replace the model. You would lose the ability to explain what changed.
Before building, write a short decision record: the eligible task, the blocked handoff, the evidence, the proposed change and the result that would make you keep or reject it. Add an owner and an observation window suited to how often the task occurs.
Treat the AI adoption framework as a way to choose an experiment, not as proof that your diagnosis is correct. Your test should be capable of disproving it.
Measure application among users who received an output, alongside verification effort. Add a quality guardrail by reviewing a sample of applied briefs for unsupported claims. Faster acceptance is not progress if users stop checking important errors.
Also inspect the next handoff. If more people apply briefs but correction work rises later, you may have moved the burden rather than removed it. A useful result combines task completion, acceptable quality and manageable user effort.
If the team cannot agree on the test, use a workshop around the broken user flow to turn the evidence into one concrete decision, rather than a backlog of unrelated improvements.
Frequently asked questions
How is this different from an organizational adoption framework? An organizational framework addresses capabilities, governance and rollout. This AI adoption framework focuses on a shipped product: where a qualified user stops progressing toward a useful outcome. Both can matter, but they answer different questions.
What if we do not have detailed instrumentation? Observe a small set of eligible tasks from start to finish, including failed attempts. Use those observations to form a hypothesis, then instrument the handoff you need to test. Do not treat a small sample as a reliable estimate of prevalence.
Where should we start if several symptoms appear together? Use the free Triage tool to begin narrowing the symptom, then check the diagnosis against actual attempts. Several visible symptoms may come from the same earlier failure.
Leave with one decision
Choose one task and write: “Users reach ___, but cannot proceed because ___. We will test ___ and check ___.” If you cannot fill the gaps with evidence, investigate before prescribing.
For deeper work, the AI Product Adoption Deck provides a 104-card, 124-page diagnostic playbook with 12 diagnostics, 80 action cards across 10 stacks and 12 workshops with fillable deliverable templates. Use it to turn the identified break into a concrete product decision.