A Diagnostic AI Workflow for Separating Symptoms From Causes
Use a diagnostic AI workflow to separate adoption symptoms from causes, test competing explanations and choose the next product change.
Users generate an answer, inspect it, then finish the task without it. Your dashboard calls this low adoption. Your team calls it a quality problem. Neither label explains what happened. A diagnostic AI workflow should separate the behavior you observed from the cause you suspect, then identify what evidence would distinguish that cause from its alternatives.
The deliverable is not a longer list of possible problems. It is a defensible decision about what to test next.
Define the observation before explaining it
“Users don’t trust the output” is already an explanation. Start one level below it.
A usable observation names the user, task, behavior and boundary of your evidence. For example: “Among support agents who generated a reply for an eligible ticket, some inspected the draft but sent a manually written response instead.”
That statement leaves several explanations open. The draft could contain errors. It could require too much checking. It could be difficult to edit or move into the reply composer.
Record the denominator, too. Comparing application rates across all accounts can hide differences in task eligibility, permissions or access to relevant context. Compare similar opportunities to use the feature, not just people who opened it.
Your first artifact should be an observation that another teammate could verify without accepting your interpretation. Keep assumptions in a separate field.
Build a diagnostic AI workflow around competing explanations
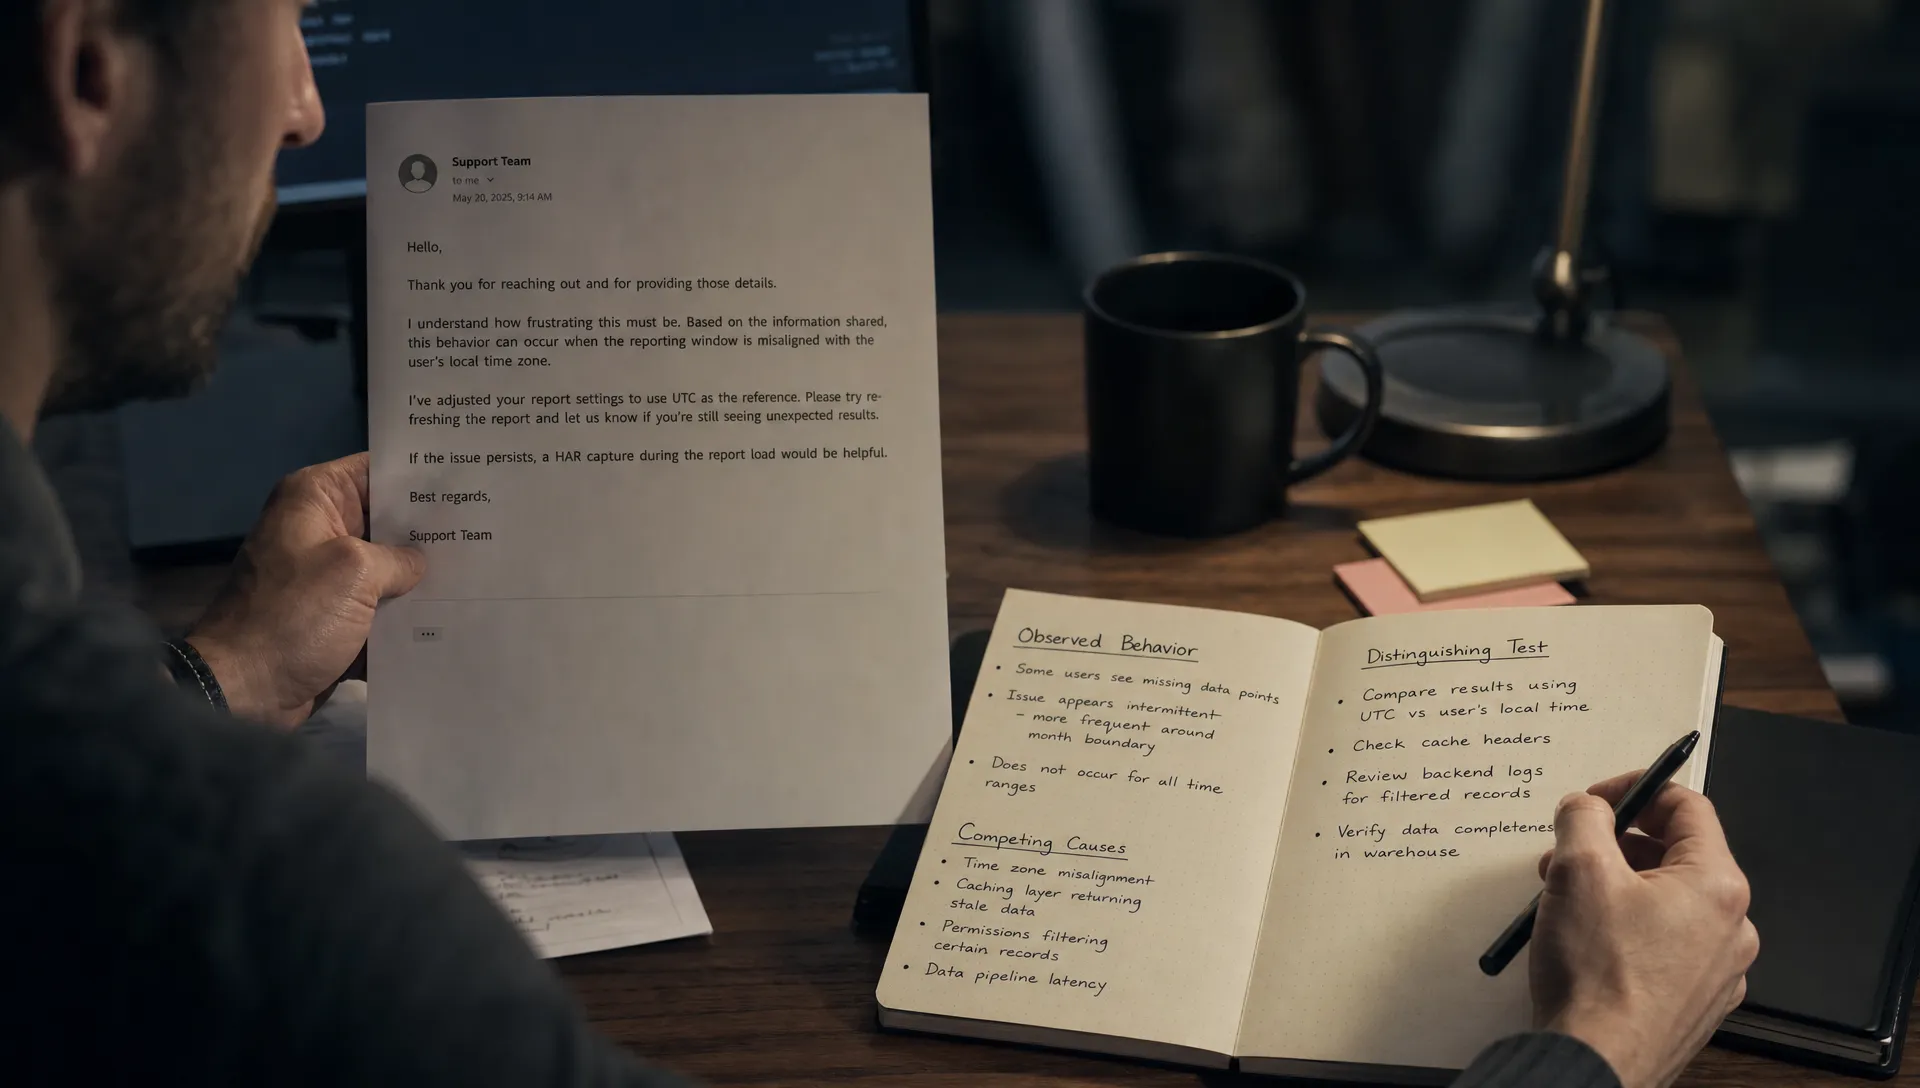
Write down competing causes before choosing a fix. Otherwise, the first plausible explanation tends to become the roadmap.
For the abandoned support reply, a hypothesis ledger might look like this:
| Possible cause | Evidence you would expect | Test that could distinguish it |
|---|---|---|
| Missing ticket context | Drafts omit facts available elsewhere in the account | Compare drafts with and without the missing context, using a task-specific review rubric |
| High verification burden | Agents repeatedly consult policy documents before rejecting otherwise usable drafts | Expose relevant source passages while keeping the draft unchanged |
| Correction friction | Agents abandon drafts after trying to change one detail | Make the same draft editable in the reply composer |
These are hypotheses, not findings. Several can be true at once.
Add a field for evidence against each explanation. If agents reject drafts they consider accurate, missing context is unlikely to explain those particular episodes. That does not prove an editing problem, but it narrows the next investigation.
Reconstruct the task, not just the funnel
An event sequence tells you that someone generated, regenerated and left. It does not tell you whether regeneration meant dissatisfaction, exploration or comparison.
Review task episodes across different outcomes: applied unchanged, edited and applied, abandoned after inspection and never generated. Include unsuccessful episodes, not just enthusiastic users who volunteer feedback.
For each episode, connect the input, available context, generated output, correction attempts and downstream action. Check whether your instrumentation misses copying or application outside the product. A missing event is not evidence of abandonment until you understand that boundary.
A diagnostic AI workflow becomes useful when it connects these records to the user's task rather than treating clicks as explanations.
Ask people to walk through a recent episode: “What did you check before deciding not to use this?” is more informative than “Do you trust AI?” The first question can reveal a specific cost. The second invites a general opinion.
Use AI to organize evidence, not certify a cause
AI can help group episode notes and retrieve examples for each hypothesis. Give it evidence IDs and require every proposed pattern to point back to a record. Ask it to separate observations, interpretations and missing information.
Do not treat repeated wording as independent confirmation. Five support tickets may describe one customer's incident. A polished summary can hide that duplication.
Keep the evidence ledger outside the generated summary so someone can audit the reasoning. The distinction between organizing evidence and asserting certainty is explored further in where AI-assisted diagnosis helps and where it breaks.
Choose a test that separates competing causes
A useful test changes something the suspected cause predicts should matter. It should also leave the main alternatives as undisturbed as practical.
Suppose you suspect verification burden. Showing relevant policy passages beside an unchanged draft is more informative than simultaneously changing the model, prompt, editor and onboarding. If application improves after that bundle, you will not know which change mattered.
Write the prediction before running the test: “For eligible tickets, source visibility should reduce checking effort and increase applied replies without increasing policy errors.”
Measure the task outcome, not just interaction with the new control. Source clicks show that people opened sources. They do not establish that replies became easier to use.
Pair application with a quality guardrail, such as a qualified review of factual and policy correctness. More acceptance can also mean less scrutiny.
Where traffic permits, use a controlled comparison with comparable task opportunities. With limited traffic, observed sessions can reveal whether the proposed mechanism exists, but they cannot establish a reliable lift estimate.
Read the result without rewriting the hypothesis
A diagnostic AI workflow needs an explicit rule for interpreting mixed results. Otherwise, almost any movement becomes evidence that the team was right.
If source visibility reduces checking effort but application stays flat, verification burden may be real without being the constraint blocking use. Examine what happens next. Agents might now verify quickly but still struggle to correct the draft.
If application rises while quality deteriorates, do not call the test a success. You may have encouraged overreliance rather than removed unnecessary work.
If nothing changes, inspect whether people encountered the intervention and whether it actually changed their ability to verify. A control nobody notices is a weak test of the underlying explanation.
Record the conclusion narrowly: “This test supports verification burden for these tasks” is more defensible than “We solved trust.” Preserve unresolved alternatives instead of deleting them from the ledger.
Turn the diagnosis into a product decision
End the review with a short decision record: the observed symptom, current explanation, supporting and conflicting evidence, next change and condition for reconsidering it.
For the support example, that could mean testing in-composer editing after source visibility reduced checking time but left correction abandonment unchanged.
Assign one owner to the next test. Keep the task cohort and quality guardrail explicit. This prevents a narrow finding from becoming a product-wide redesign justified by “users don’t trust AI.”
Frequently asked questions
Is this the same as evaluating model quality? No. Model evaluation examines output performance against defined criteria. Adoption diagnosis asks why an output is or is not used in a real task. Output quality is one possible cause, not the default explanation.
What if several causes appear together? Identify the next constraint that prevents task completion. Test that constraint without assuming it is the only one. Removing it may expose another break later in the workflow.
Start with one abandoned task
Use this diagnostic AI workflow on a concrete episode before expanding it across the product. If you need help choosing the starting symptom, use the free Triage tool.
For deeper follow-through, the AI Product Adoption Deck provides a 104-card, 124-page playbook with 12 diagnostics, 80 action cards across 10 stacks and 12 workshops. Use it to turn the selected adoption problem into a concrete product decision or experiment.