The AI Problem Hidden by Feedback From Power Users
Uncover the AI problem hidden by power-user praise. Diagnose expert workarounds, compare user cohorts and test what blocks broader adoption.
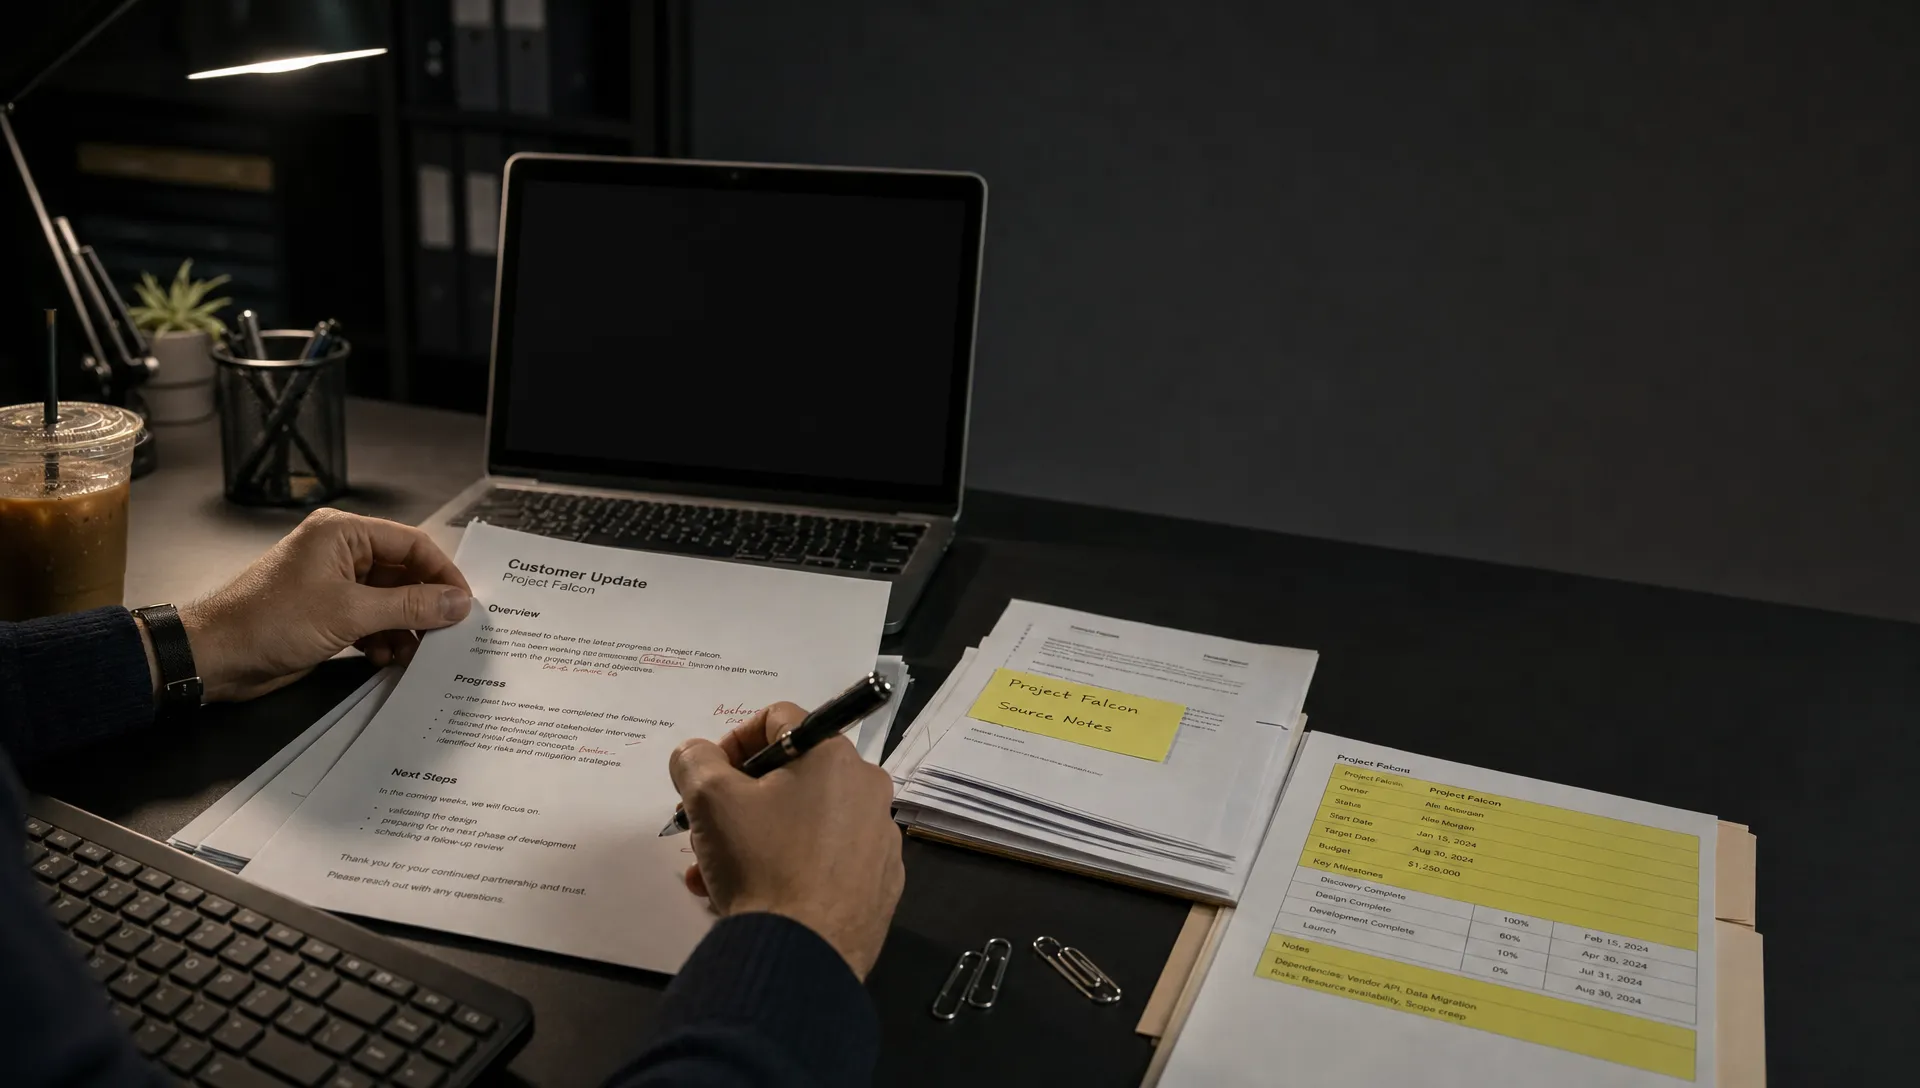
Your heaviest users ask for more flexibility. They praise the output, request advanced controls and tell you the feature saves time. Meanwhile, most eligible users try it once and disappear. That praise can hide the AI problem you need to solve: experienced users have learned to compensate for a product that leaves everyone else stuck.
Their feedback is not wrong. It describes a successful relationship with your feature. But it may leave out the prompting, verification and repair work that makes that relationship possible.
Positive feedback can come from a filtered sample
Power users are valuable research participants. They expose limits, discover useful applications and explain complex workflows. The mistake is treating their success as evidence that the basic experience works.
Frequent use, product fluency and domain expertise are different things. A frequent user may still accept incorrect output. A domain expert may catch errors immediately but struggle with your interface. Someone determined to make AI work may tolerate setup that other users reasonably reject.
Your feedback channels can filter for those differences. The people attending office hours or answering roadmap surveys have already stayed long enough to participate. Users who could not reach a useful result may never explain why.
Treat power-user feedback as evidence about a segment, not a verdict on the whole experience.
How power users conceal the AI problem
Consider a hypothetical AI feature that drafts customer updates from project notes.
An experienced account manager selects relevant notes, removes outdated details and supplies examples of the right tone. After generation, they catch an unsupported claim and rewrite the closing paragraph. They report that the feature is useful.
A newer colleague selects the same project and asks for an update. The draft sounds plausible, but they cannot tell which statements came from the notes. They abandon it rather than risk sending something wrong.
The first user supplied context, editorial judgment and quality control. Their success does not establish that the feature provides those capabilities.
This becomes a roadmap problem when the team responds only to the successful user's requests. More controls may make an expert faster without helping the colleague reach a safe first result. You improve the experience for people who crossed the barrier while leaving the barrier intact.
Find the work successful users are supplying
To locate the AI problem, look for effort that disappears from the feedback summary. Ask users to show their last completed task, including what happened before generation and after the response appeared.
| Observed symptom | Possible expert workaround | What to inspect next |
|---|---|---|
| Strong praise, weak first-task completion | Experienced users know what context to supply | Compare inputs before the first useful result |
| Good output ratings, little downstream use | Experts quietly repair drafts before using them | Observe editing and the final handoff |
| One active champion per account | The champion prepares prompts or checks colleagues' work | Watch another team member complete the task independently |
| Frequent regeneration among newer users | Experts know how to describe a specific correction | Check whether users can identify and repair one defect |
These are hypotheses, not conclusions. Regeneration might reflect exploration rather than failure. Editing might be the intended workflow rather than unwanted rework. The useful distinction is whether the effort advances the task or compensates for a missing product capability.
Ask one revealing question: “What have you learned to do that makes this feature work?” Then observe that behavior rather than relying on the explanation alone.
Measure completion and effort by cohort
Separate experienced repeat users from first-time users attempting the same job. Within those groups, account for domain knowledge, access to relevant information and the consequences of a mistake.
Compare task completion, time spent preparing inputs, verification effort, correction attempts and whether the result reaches its intended destination. Keep generation counts as context, not proof of success.
The AI problem becomes clearer when you measure the work required to reach a usable result, rather than stopping at a positive output rating. A draft can receive a thumbs-up and still require too much checking to be worth using again.
When checking AI output is too expensive, experts may absorb that cost because they know where to look. Less experienced users may abandon the result or, more dangerously, accept errors they cannot recognize. Acceptance alone does not establish correctness.
For retention, check whether users return when the relevant task recurs. Daily usage is not a useful expectation for a monthly workflow.
Run a matched-task study before changing the roadmap
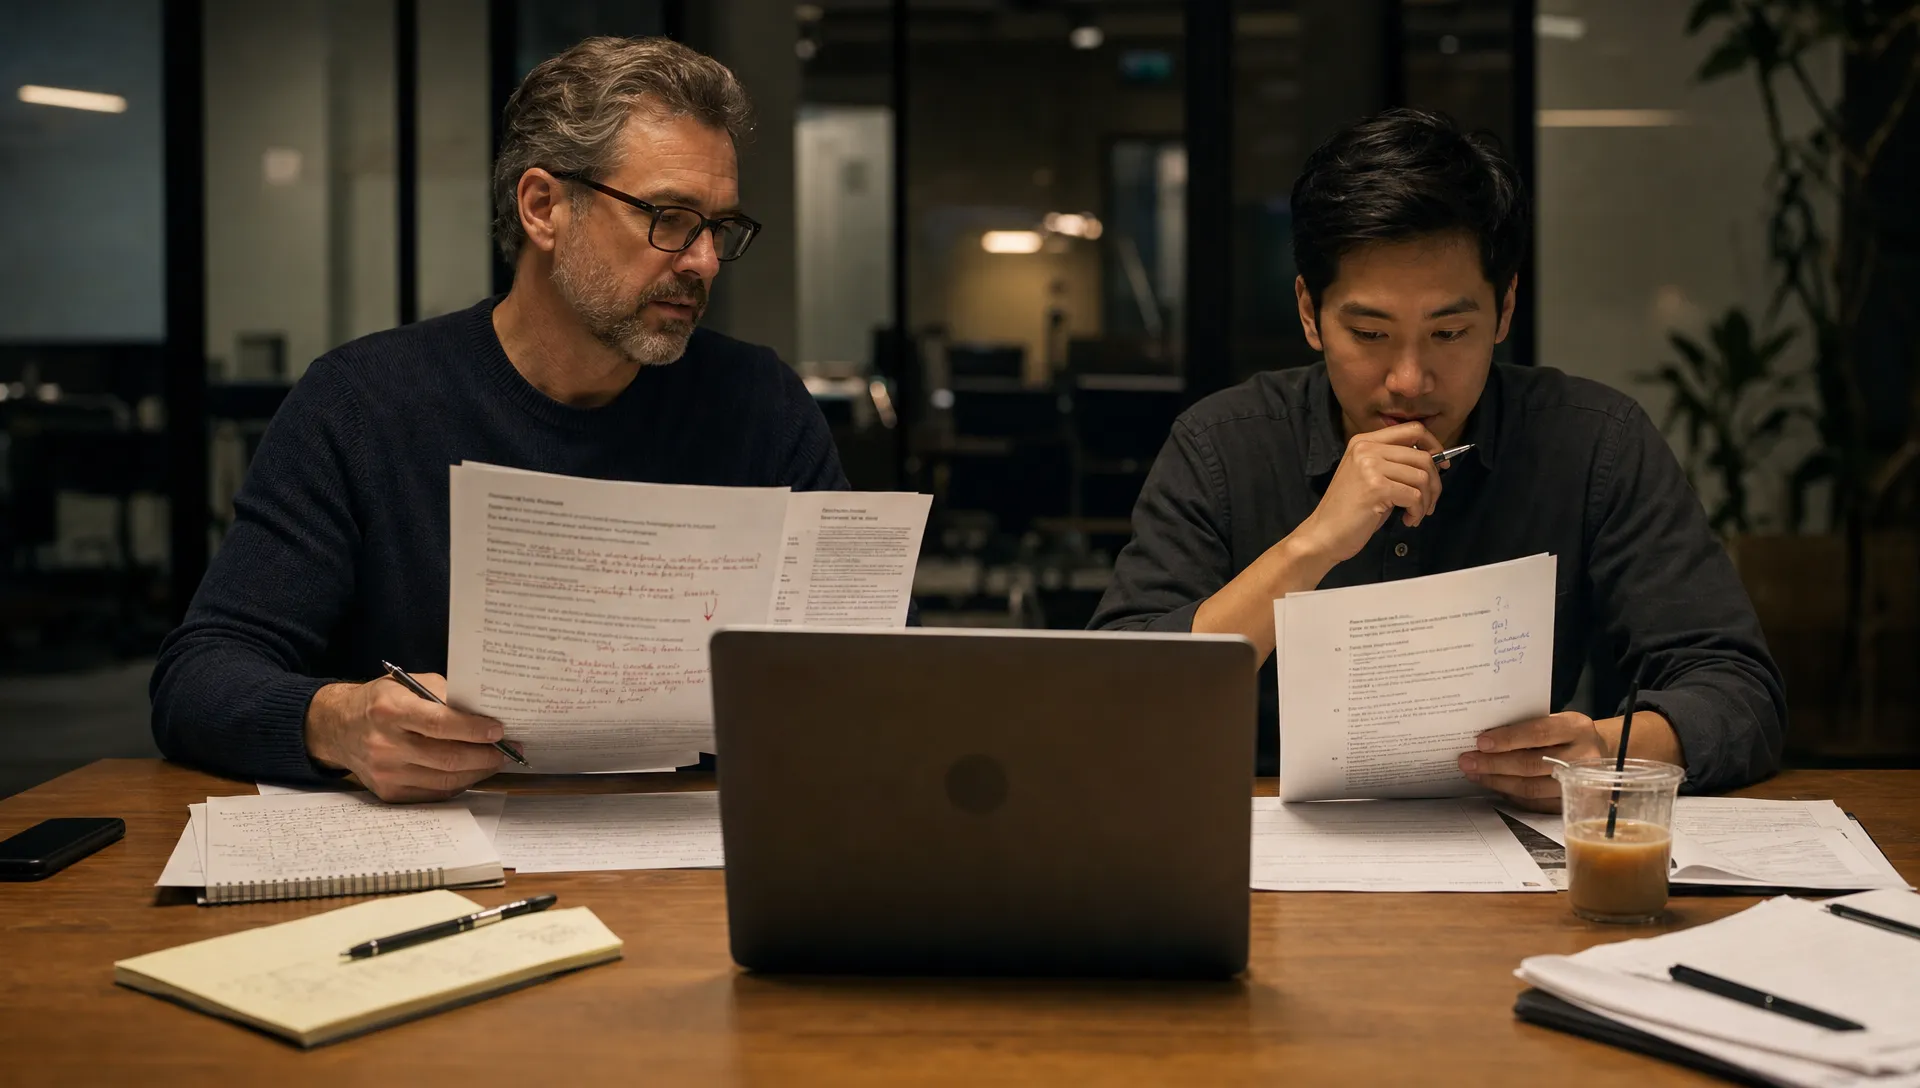
Recruit from both sides of the adoption gap, including people who tried the feature and stopped. A practical first study can be small, but treat its findings as directional rather than a population estimate.
Hold the job steady
Give participants comparable tasks with similar source material, permissions and output stakes. Do not compare an expert's private brainstorming session with a newcomer's customer-facing deliverable. Agree beforehand on what counts as a usable result.
Observe the whole attempt
Start before the prompt. Watch how participants choose material, decide what to ask, inspect the answer and move it into their workflow. Capture only approved information and avoid collecting sensitive source content unnecessarily.
Let participants try without coaching first. Then offer one targeted intervention, such as a context checklist or source-linked claims. This helps test whether the AI problem involves missing support that an expert has learned to provide independently.
Test the suspected dependency
If newcomers stall while experts succeed, identify the specific behavior separating them. Test a product change that supplies that support. Use fresh participants or equivalent tasks so familiarity does not masquerade as improvement.
Look for usable completion with less compensating effort. Faster generation or higher confidence is not enough if the final result is still wrong.
Decide whether to support, simplify or narrow
Different findings call for different decisions.
If users cannot supply the right context, test structured inputs or clearer scope. If they cannot judge the result, test accessible evidence and task-specific checks. If they can identify an error but cannot fix it, improve the correction loop before adding more generation options.
Do not assume every gap should disappear. Some products legitimately serve specialists. If domain expertise is necessary to use the output safely, make that requirement explicit and align onboarding, positioning and success measures with that audience.
Otherwise, the AI problem remains hidden behind an expert-only definition of success. You may be selling a broadly accessible workflow while measuring only the people qualified to supervise it.
Keep power users involved, but separate their advanced requests from the changes needed for reliable first-task completion. Both deserve evidence. They do not need the same roadmap priority.
Frequently asked questions
Should we stop interviewing power users? No. Use them to discover valuable tasks, advanced needs and learned workarounds. Pair their feedback with observation of eligible users who stalled or left.
How do we distinguish a skill gap from a product problem? Test whether reasonable support helps the intended audience complete the task safely. If success requires specialist judgment, decide whether to serve specialists explicitly or redesign the task. More onboarding cannot substitute for expertise users do not have.
Start with one successful task and one abandoned task
Observe both attempts. Identify one compensating behavior, then decide whether the product should provide that support or require it explicitly.
If you need a starting point, the free Triage tool can help diagnose the symptom. For deeper work, the AI Product Adoption Deck provides 12 diagnostics, 80 action cards and 12 workshops with fillable deliverable templates. Use the diagnosis to choose a concrete change, not another round of broad feedback collection.