Product Management for AI & Data Science When User Segments Diverge
Product management for AI & data science when segments diverge: diagnose uneven adoption, compare task outcomes and choose targeted fixes.
Your AI feature saves one group time and gives another group extra review work. The blended retention chart barely moves. In product management for AI & data science, that pattern calls for a segment-level diagnosis before you change the model.
Consider a hypothetical support-drafting feature. Less experienced agents accept its suggestions quickly. Experienced agents rewrite them. Quality reviewers flag mistakes in some accepted replies. Those behaviors do not tell you which group benefits. Fast acceptance can hide missed errors. Heavy editing can reflect either useful assistance or wasted effort.
The question is not which segment likes AI. It is which users complete which tasks better, under which conditions.
Segment the work, not just the customer
“Enterprise versus small business” may help explain purchasing behavior. It rarely explains why an AI answer gets used, corrected or abandoned.
Start with differences that could change the outcome: the task, the user's ability to verify the answer, the consequences of an error and the quality of available inputs. Treat each as a hypothesis, not a permanent user label.
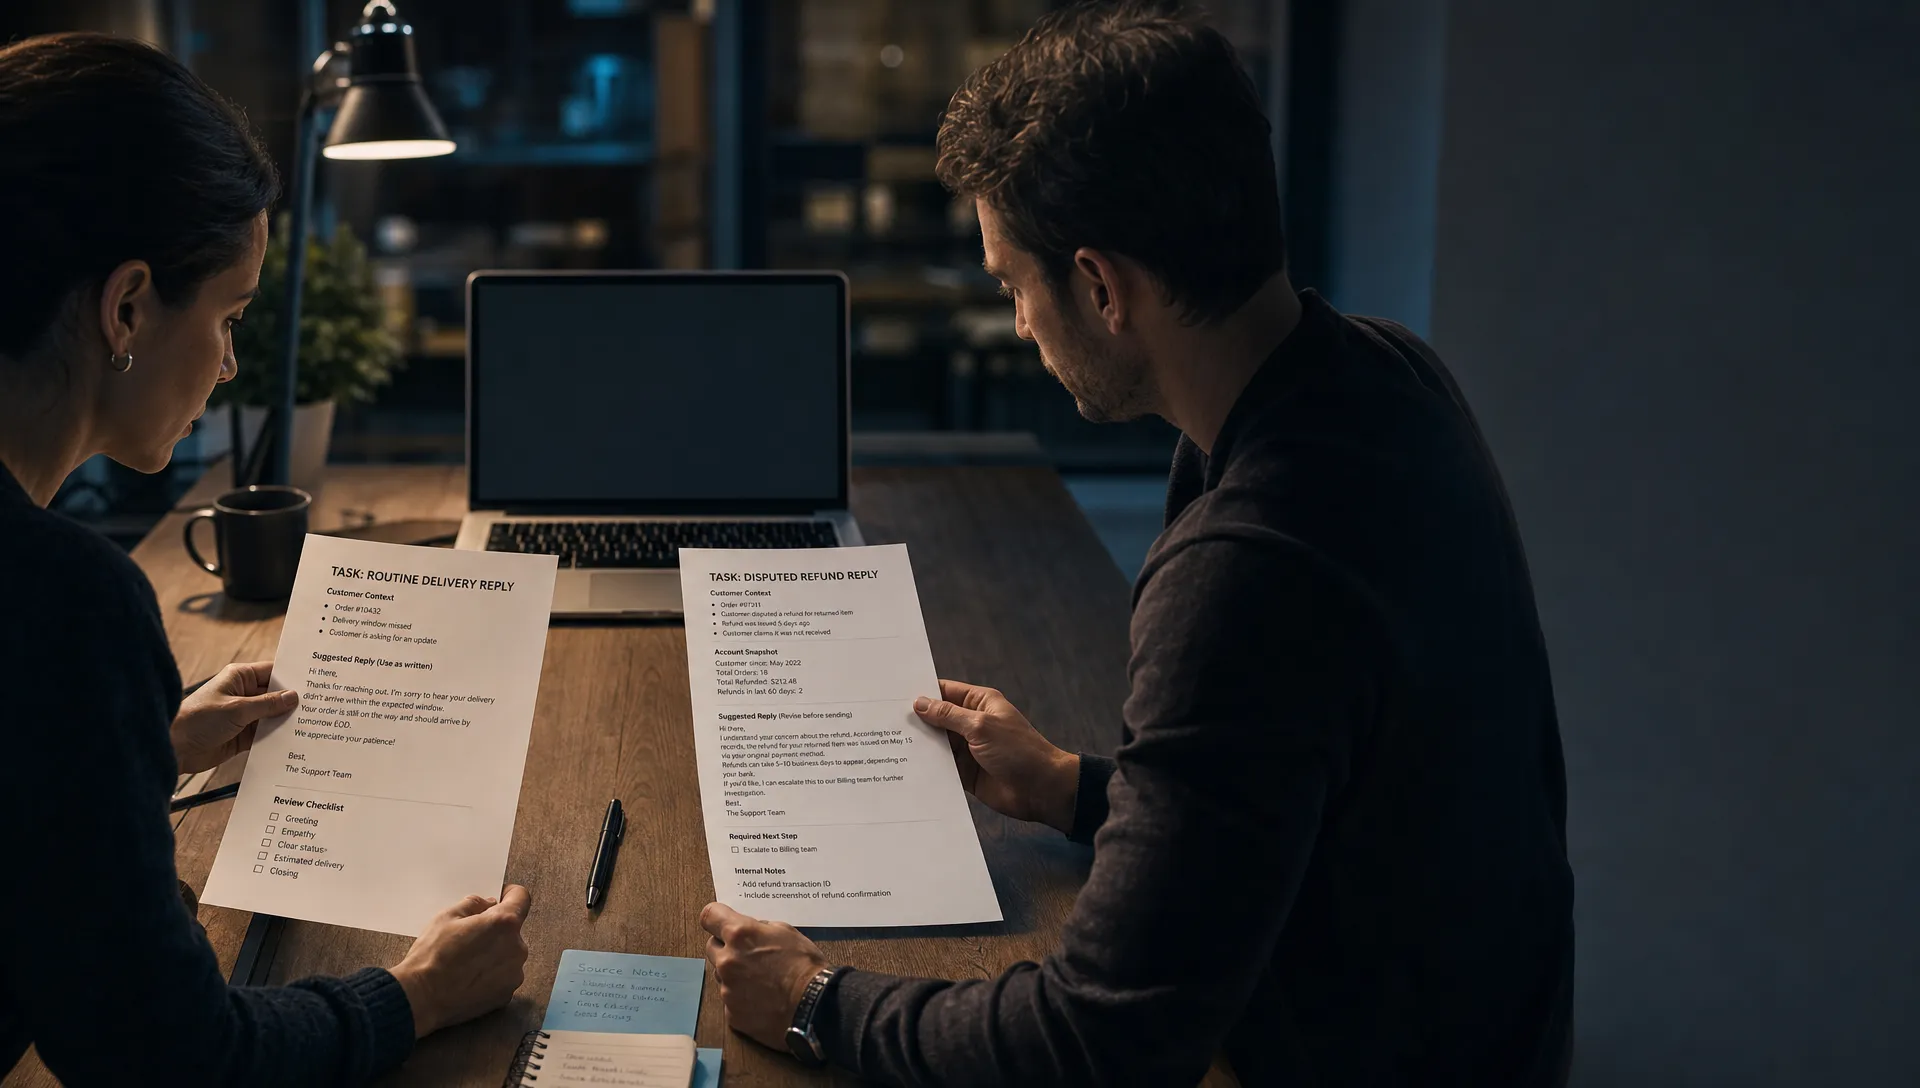
In the support example, drafting a routine delivery update is different from handling a disputed refund. The same experienced agent may welcome automation for the first and reject it for the second. Segmenting only by tenure would hide that distinction.
Write a task-level promise for each group you investigate. For example: “Help agents produce an accurate routine reply faster, while preserving required checks.” A sensitive-case segment needs a different promise, with explicit review requirements.
Start with a few plausible segments. Crossing every account attribute with every behavior produces small groups that are difficult to interpret.
Product management for AI & data science needs matched denominators
Compare outcomes for comparable opportunities, not just people who clicked the AI button. Otherwise, you may compare easy tasks selected for AI with harder tasks handled manually.
Build a compact scorecard for each task segment:
| Measure | Definition | What it helps diagnose |
|---|---|---|
| Eligible opportunities | Tasks where the feature could reasonably help | Whether users had a reason to use it |
| Successful task completion | Eligible tasks completed to an agreed quality standard | Whether assistance creates usable outcomes |
| Total completion time | Time spent preparing, generating, checking, editing and recovering | Whether AI saves work overall |
| Consequential error rate | Reviewed outcomes containing predefined serious defects | Whether apparent speed hides unacceptable risk |
| Repeat use per opportunity | Use across subsequent eligible tasks | Whether assistance earns a place in the workflow |
Keep the comparison window and quality rubric consistent. Where feasible, use randomized access or another credible baseline within each segment. If colleagues share drafts or working practices, account-level assignment may be more appropriate than individual assignment.
Include eligible non-users in adoption analysis. Looking only at generated outputs excludes people who tried the feature, lost confidence and stopped opening it.
Report raw counts alongside rates. A segment with six completed tasks does not provide the same evidence as one with hundreds. Differences may also reflect account mix or task difficulty rather than the feature itself.
Separate verification burden from output quality
The diagnostic work in product management for AI & data science is connecting a behavior to its cause. An acceptance rate alone cannot do that.
Suppose experienced agents reject drafts because the output omits account-specific commitments. Inspect whether those commitments were available to the feature. Missing context suggests an input or workflow problem. Ignoring supplied context suggests a quality problem. Producing correct content that is difficult to inspect suggests a presentation problem.
Those causes require different responses. A broader prompt box does not repair missing account data. A model change does not necessarily make a correct answer easier to verify.
Now inspect the less experienced group. High acceptance combined with serious downstream corrections is not successful activation. Users may lack the knowledge needed to spot a plausible error. Removing review friction could make that segment less safe without making it more effective.
Finally, examine heavy editors. Compare their total completion time and final quality with the baseline. Editing can be productive collaboration. It becomes a failure when users spend more effort repairing the draft than they would spend doing the task themselves.
To distinguish these cases, capture rejection reasons and what users do afterward. Pair observed behavior with a review of the actual input, output and completed task. Do not infer the cause from the click alone.
Choose the smallest product change that fits the diagnosis
Good product management for AI & data science does not require a separate product for every segment. Start with the smallest change that addresses the observed cause.
For routine tasks with reliable inputs and acceptable outcomes, an inline suggestion may be sufficient. For tasks requiring source verification, place relevant evidence beside the claim it supports. For consequential actions, keep a meaningful approval step and a clear route back to manual work.
If missing context drives rejection, improve the input handoff before adding more generation controls. If users cannot judge correctness, provide appropriate review support rather than treating acceptance as informed approval.
Prefer routing based on task conditions or explicit user choices over assumptions about who a person is. “This reply involves a disputed payment” is a more useful trigger than “this user is junior.” Allow overrides where appropriate, without removing necessary safeguards.
Do not collect sensitive attributes merely to make segmentation more detailed. Use data with a clear diagnostic purpose, appropriate access controls and a defined retention policy.
Make release decisions at segment level
Before testing a change, write down what would justify expanding, revising or stopping it for each segment. Choose a primary task outcome and explicit guardrails.
For routine replies, the outcome might be lower total completion time without worse reviewed accuracy. For sensitive cases, acceptable error levels and required oversight may take precedence over speed. Set those conditions before examining results.
A release decision in product management for AI & data science should not let gains in a large, low-risk segment cancel out unacceptable harm in a smaller one. If a segment fails its guardrails, restrict or pause that use case while investigating it.
When evidence is sparse, narrow the rollout and preserve review. “We have not observed a serious error” is not the same as demonstrating that the risk is acceptable.
Recheck the scorecards after changes to output behavior, available data or interface defaults. Keep a manual fallback so an affected segment can continue working while the team diagnoses a regression.
Frequently asked questions
Should every user segment get a different model? No. First establish whether the difference comes from inputs, task requirements, verification needs or workflow fit. Different models are only one possible response.
What if a segment uses the feature infrequently? Compare use with eligible opportunities. A feature for an occasional task can be valuable without becoming a daily habit.
When should we stop splitting segments? Stop when another split no longer changes a product decision or leaves too little evidence to interpret. Keep the analysis focused on actionable differences.
Make one segment-level decision this week
Choose two groups with different outcomes. Review comparable tasks, calculate total completion effort and identify the most consequential failure in each. Leave the review with one decision: a shared fix, a task-specific experience or a restricted rollout.
If the failure point is still unclear, use the free AI adoption Triage tool to start the diagnosis. For a more structured team exercise, the AI Product Adoption Deck provides a 104-card diagnostic playbook with 12 diagnostics and 12 workshop templates. Use the structure to turn the observed difference into a concrete product decision.